Monday, March 10, 2014

Why do we think P NE NP? (inspired by Scott's post)

Recently  Scott Posted an excellent essay on reasons to think that P NE NP.  This inspired me to post on the same topic. Inspired is probably the right word. Some of my post is  copied and some of my post   are my thoughts. A good test: if its intelligent and well thought out then its probably from Scott.

Why do scientists believe any particular theory?  I state three reasons, though there are likely more:
(1) By doing Popperian experiments- experiments that really can fail. Their failure to fail helps to confirm the theory. This is common in Physics, though gets harder when the particles get smaller and string-like. (2) Great Explanatory power. Evolution is the main example here--- it's hard to do real experiments but one can look at the data that is already out there and find a theory that explains it all. (3) (Kuhn-light) It fits into the paradigm that scientists already have. This comes dangerously close to group think; however, if most of the people who have looked at problem X think Y, that should carry some weight.

Can we do Popperian experiments for P vs NP? For that matter can we do Popperian experiments in Mathematics? Goldbach's conjecture and the Riemann Hypothesis seem to have good empirical evidence. Though that kind of reasoning gets me nervous because of the following true story: Let li(x) = int_0^x dt/ln t.
Let pi(x) be the number of primes \le x. It is known that li(x) and pi(x) are VERY CLOSE. Empirical evidence suggested that li(x)  \le  pi(x) and this was conjectured. Skewes proved that there was an x  for which li(x) \ge  pi(x). His bound on x, the the Skewes' number ,was quite large, at one time the largest number to appear in a math paper (that record now belongs to  Graham's Number). Then Littlewood, Skewes's advisor, showed that the sign of li(x)-pi(x) changes infinitely often. So the empirical evidence was not indicative.

There might also be empirical tests you can do for continuous math, especially if its related to physics so you can do physics experiments.

Have there been Popperian experiments to try to verify P NE NP? I am not quite sure what that means, but I do not think there have been (if I'm wrong please comment politely).

So we move on to Great Explanatory Power. Are there many different empirical facts out there for which P NE NP would explain them and give a unifying reason? Does a bear... Well, never mind, the answer is YES! I give one  examples (from Scott's post) and two more. But note that there are MANY MANY MORE.

  1. Set Cover problem: Given S_1,....S_m \subseteq {1,...,n} find the size of the smallest subset of S_1,...,S_m that covers the union of S_1,...,S_m. Chvatal showed in 1979 that one can find, i poly time, a subset of S_1,...,S_m that is (ln n)+OPT. Okay, great, an approximation. EMPIRICAL FACT: people seemed unable to improve on this at all. In 2013 Dana Moshkovitz proved  that, assuming P\ne NP, this bound CANNOT be broken. Note that the algorithm of Chvatal and the lower bound of Moshkovitz have nothing to do with each other.
  2. Vertex cover: given a graph find the smallest set of vertices so that every edge has   one of them as an endpoint. There is an algorthm that gives 2OPT. There is one that does ever so slightly better: (2-(1/sqrt(log V))OPT.  In 2005 Dinur and Safra proved that, assuming P NE NP, there is no 1.36*OPT approximation. This does not match exactly but it still explains the lack of progress somewhat (more on this later when I discuss UQC).
  3. Max 3-SAT: given a 3-CNF formula find an assignment that maximizes the number of clauses satisfied.  Karloff and Zwick proved that there is an algorithm that finds an assignment satisfying (7/8)*OPT. Hastad proved that, assuming P NE NP, (7/8)*OPT is the best you can do.
A bit more prosaic: P NE NP explains why people have had a hard time solving THOUSANDS OF PROBLEMS. I am most impressed with HAM CYCLE since mathematicians had been working on that one for quite some time--- trying to get a similar char to that of EULER circuit.

So in summary, I find that P NE NP has GREAT explanatory power. That makes it a very compelling conjecture. Let us apply this test to other conjectures.

  1. Sigma_2 \ne Pi_2. Does this assumption explain anything? Our inability to find a circuit for SAT. I dont know what else it implies. Same for Sigma_i vs Pi_i. This might qualify as mini-kuhnian: Sigma_2\ne Pi_2 fits into how we view the world.
  2. P=BPP.  Almost every problem in BPP ended up falling into P over time. P=BPP would explain this. Also Nisan-Wigderson and its extensions make P=BPP fit into our world view.
  3. Unique Game Conjecture. This explains many upper and lower bounds that match, though nowhere near that of P NE NP. One of them is the constant 2 for VC. Even so, I find that compelling. (One of Scott's commenters said that all of the lower bounds from UGC are actually unified some how, so its not quite as compelling.)
  4. Factoring not in P. No real explanatory power here except that we seem to have a hard time finding an algorithm for Factoring. 
  5. Graph Isom not in P. Similar to Factoring not in P.
So, what are our reasons to think Sigma_2 \ne Pi_2?

Lastly, mini-Kuhnian. What do people in the field think? The polls on P vs NP that I conducted in 2002  and 2012 (see here)  indicate that believe that P NE NP is growing- roughly 60% in 2002, roughly 80% in 2012. Some of the commentators on Scott's blog took that 20% of P=NP people to be relevant.
And indeed some of the P=NP people are both serious theorists and also not Dick Lipton (who seems to be who  Lubos Motl points to) as a serious theorist who thinks P=NP).(ADDED LATER- SOME COMMENTERS HAVE INFORMED ME THAT LIPTON IS JUST OPEN TO THE POSS THAT P=NP. ) But some of those people emailed me that this was a protest vote, protesting the fields certainty that P=NP. I also note that three of them compared it to their voting or Ralph Nader in 2000, only with less drastic consequences.

I personally don't take `what people think' that seriously, but because of my polls we actually know what people think, so I put it out there.


Thursday, March 06, 2014

Favorite Theorems: Unique Games

Michel Goemans and David Williamson made a splash in the 90's using semidefinite programming to give a new approximation algorithm for the max-cut problem, a ratio of 2θ/(π(1-cos(θ)) minimized over θ between 0 and π, approximately 0.87856. Hard to believe that this ratio is tight, but it is assuming the unique games conjecture.
The first paper showed that the Goemans-Williamson bound was tight assuming the unique games conjecture and a "majority is stablest conjecture", the last says very roughly that the most robust election scheme is a simple majority. The second paper, which followed soon thereafter, proved an invariance property that implies, among other things, that indeed majority is stablest.

Khot and Oded Regev show that under the unique games conjecture that essentially the best algorithm for approximating vertex cover is to take all the vertices involved in a maximal matching.

Prasad Raghavendra gives a simple semidefinite programming approximation algorithm for any constraint satisfaction problem which is optimal under the UGC.

Sanjeev Arora, Boaz Barak and David Steurer describe an algorithm that given a unique game where 1-δ fraction of the edges can be satisfied, you can in time 2npoly(δ) find a coloring that satisfies a constant fraction of edges. This may or may not give evidence against the UGC.

Luca Trevisan has a nice recent survey on the unique games conjecture, covering much of the above and more, including beautiful connections between unique games and semidefinite programming.

Tuesday, March 04, 2014

Why are there so few intemediary problems in Complexity? In Computability?


There are thousands of natural PC problems. Assuming P NE NP how many natural problems are there that are
in NP-P but are NOT NPC? Some candidates are Factoring, Discrete Log, Graph Isom, some in group theory, and any natural sparse set. See
here for some more.

A student asked me WHY there are so few natural intermediary problems. I don't know but here are some
options:

  1. Bill you moron, there are MANY such problems. You didn't mention THESE problems (Followed by a list of problems
    that few people have heard of but seem to be intermediary.)
  2. This is a question of Philosophy and hence not interesting.
  3. This is a question of Philosophy and hence very interesting.
  4. That's just the way it goes.
  5. By Murphy's law there will be many problems that we can't solve quickly.

At least in complexity theory there are SOME candidates for intermediary sets.
In computability theory, where we know Sigma_1 \ne \Sigma_0, there are no
candidates for natural problems that are c.e., not decidable, but not complete. There have been some attempts to show that there can't be any
such sets, but its hard to define ``natural'' rigorously. (There ARE sets that are c.e., not dec, not complete, but they are
constructed for the sole purpose of being there. My darling would call them `dumb ass' sets,
a terminology that my class now uses as well.)

A long time ago an AI student was working on classifying various problems in planning. There was one that was c.e. and not decidable
and he was unable to show it was complete. He asked me to help him prove it was not complete. I told him, without looking at it,
that it was COMPLETE!!!!!!!!! My confidence inspired him to prove it was complete.

So, aside from the answers above, is there a MATH reason why there are so few
intermediary problems in Complexity, and NONE in computability theory?
Is there some other kind of reason?

Thursday, February 27, 2014

Why Become a Professor

Someone took me to task because in November I posted that the CRA News had 50 pages of job ads but didn't note that very few of those ads specifically were searching for CS theory faculty. Yes, it is true that theory is not as high on the search agenda as big data and other applied areas, but many of these schools will hire theorists after they fail to find qualified applicants in the other areas. My advice is to apply widely and it's not too late to do so, as many CS departments are just starting their interview process.

Why is it so hard for universities to hire in applied CS? Because you are not just competing against other universities, you are competing against industrial labs. Besides the usual arguments of typically hire base salary and no required teaching or grants, a place like Facebook or Google can give you access to data that you just can't get a university and your research will have a real-world impact faster than basic academic research.

So why be a professor? Money isn't as big an issue as you expect, professors can consult, own significant portions of their IP (depending on the school) and can start companies. Teaching is time-consuming but extremely rewarding. To me there are two aspects that make being a professor the best job in the world.

  • Freedom to set your own research agenda: Very few labs these days give you the freedom to choose your own research topics and even fewer will reward you for that. In academics we expect you to develop your own research areas and succeed in them. 
  • Working with students: The relationship between advisor and advisee is not unlike a parent and child. And there's no better feeling than watching them succeed. You can often get summer interns and postdocs in industry but it just isn't the same.

Sunday, February 23, 2014

When is a paper public? When is anything public?

A while back I had a paper in an intermediary stage. The version posted to my Ramsey Theory Course Website was not final. Is the paper public? I didn't think about it much but I didn't intend it to be since it was not done yet. But Adam Sheffer's Google Scholar (more on that later) didn't know that. So his Google Scholar program found the paper and he blogged about it here.

This was FINE- my co-author David Conlon posted a comment on the blog that a revised version was coming, and I asked Adam to modify the blog to say so as well. Plus, I am DELIGHTED and SURPRISED when someone noticed my work.
When the final version came out Adam DID report about it here.
But it raises the question- when is a paper public? Some related thoughts
  1. (Kudos to Adam for pointing me to this one). I had heard the ABC conjecture might be solved. What I didn't quite know is that the author posted the papers on HIS OWN website, not on arXiv. Did he intend for it to go public? I do not know- but it is NOW public. If its not correct he can always say well, I didn't tell you it was ready for
    prime time yet
    .
  2. A while back a student pointed me to a website with a paper that claimed to show GI is in P. The author DID NOT post it to arXiv (this may have been before there was an arXiv) nor did he email GI experts across the planet to look at it. So is it public? Is it my job to debunk it? It would be a bit odd to tell someone who didn't ask my opinion that YOUR PROOF IS WRONG! The student was hoping it was TRUE so he wouldn't have to learn the proof that if GI is NPC then PH collapses. I ended up telling the student that its surely wrong else since if GI was in P then I would known it--- not a really rigorous proof, but it sufficed. See here for more on this non-rigorous proof technique.
  3. I have read stories of people who post personal things on FaceBook (a common one is that they are gay) and then are shocked, shocked, when their parents find out.
  4. There's a nice song about a related issue: My Mom's on Facebook.
  5. On the TV show West Wing there was a segment where someone thought a story was just regional and hence would not affect her confirmation hearing. She had to be told NO- there is no such thing as a story that is just regional. Journalists and others can FIND STUFF if it is out there.
  6. Similarly to the last item: I can't post a paper just for my class because Google Scholar will find it (I DO NOT EVER require a password for a course website, I don't want to hassle the students and I am happy if somone else wants to see what I am teaching. Note also that this blog is NOT complaining that Adam found my paper). I (cordially) emailed Adam Sheffer inquiring how Google Scholar found me. For my fellow Luddites I reprint his answer (hmmm, I don't know if he meant his email to be public.)
    Regarding how Google Scholar works: The system constantly scans the web for new papers. It knows the papers which I have coauthored (it finds them while searching the web and asks me to verify that they are indeed mine). Then, in future scans, if it stumbles upon a paper that might be relevant to me - it sends me and update about it. I am not sure what exactly are the criteria that it uses, but it seems to be papers by my coauthors and papers on similar topics (perhaps papers that have common references with my papers?).
    Sound like when TIVO tried to guess what shows you liked- it could be right but it could be far off. I know of liberals who watched FOX news a lot to gain insight into what people they disagree with thought, and then their TIVO thought were Tea Partiers. Then TIVO thought they liked Tea.
  7. I gave Adam kindly blogger-to-blogger advice: DO NOT let this be a cautionary tale. Do not ask permission to post about a PAPER --- just do it. I've done it here when blogging about Galois games and here when blogging about how much trig should a governor know. If you post on something a bit more personal (e.g., here) then maybe you should get permission (one of the people gave permission, the other never responded).

So what to make of all this? We are in a time of transition and some people
may end up revealing more than they intended. The next generation may learn;
however, we seem to always be in a time of transition.
"p.html" 31L, 4785C written

Wednesday, February 19, 2014

Analog Adventures

I was 11 forty years ago when Dungeons and Dragons first appeared and by high school many of my friends spent far too many hours embarking on those fantasy adventures. I didn't play much myself only joining a few campaigns for a short period of time. Nevertheless the game hit its mark, giving escapism to our inner nerdoms.

I just finished a new book on D&D Of Dice and Men by David Ewalt. Ewalt tells three interlocking stories: The history of D&D, Ewalt's personal journey into the game, and some campaigns he's embarked on from the characters' point of view.  Gary Gygax and Dave Arneson originally created the game but Dave soon left the company and was written out of the books. Gary mismanaged the company which has bounced around from various owners every since. I hadn't really kept up with D&D after college and I'm surprised that it has so many incompatible versions (reminds me of LaTeX and Python). A fifth version of D&D to unite them all is due for release this summer.

My daughter's school just put on a production of She Kills Monsters, a play about a woman who discovers her late sister through the sister's D&D adventures. My daughter played an evil cheerleader and her line "We're way too powerful for you" reminded us both of her classic role as NP.

These days we have immersive rich interactive games on our Play Stations and smart phones but still there is still nothing like gathering around a table transformed into a tavern as we meet our fellow adventurers and embark on the next quest.

Monday, February 17, 2014

Maryland looking for a Lecturer/Who teachers your intro courses?

My chairman, Samir Khuller, asked me to post our job posting for a lecturer to my blog, so I and doing it right now. I think he overestimates the power of this blog.

At Univ of MD at College Park lecturers teach most sections of our intro sequence (CS1, CS2, CS3, Discrete Math). They might sometimes do a higher level course if the need arises. They are there to mostly teach and advise students, not do research, though some do and that's certainly fine. Some have PhD's and some don't.  Note that this is a full time job--- these are not adjuncts or rent-a-profs. They are part of the department.

Is having lecturers teach the intro courses  a good idea? Overall YES; however, I would like to have professors teaching those courses once in a while, or be involved once in a while, as they may have a good idea to share with the lecturer (then again, they might  not).  Having said that, you don't see me volunteering for CS1, CS2, or CS3 (My policy: I never teach a course where I would get a B if I took it. One exception- I did once teach Graduate Algorithms and got in a bit over my head.) I do teach Discrete Math once in a while. I also like to proofread the midterm and final of whoever is teaching it. I'm NOT that good a proofreader, but I like to know what they are up to and it gives me an excuse to talk to them about the course and make sure it doesn't drift to much. I would like to think I have a good rapport with the lecturers.

Does having a PhD in CS and being a professor give one some insights on what should be in CS1,2,3 and how to teach it? I honestly don't know. My first semester at Univ of MD (1985) we were teaching program verification in CS1. I knew immediately it was a bad idea and eventually (without any input from me) the dept stopped doing that. This is a case where being a researcher may be a negative with regard to education.

I would like to think that my working in theory helps me teach Discrete Math.  It does as a source of some problems (e.g, if a paper says `by an easy induction...' that can be a problem set) but one should not get to carried away and go over their heads.


Wednesday, February 12, 2014

IEEE and the Conference on Computational Complexity

Dieter van Melkebeek, current conference chair of the IEEE Conference on Computational Complexity has set up a forum to discuss the future affiliation of the conference. Read over the manifesto and update. You can give general comments on the about post. Dieter discusses three options:

  1. Remain with IEEE
  2. Have a joint ACM/IEEE conference in some fashion.
  3. Become an unaffiliated conference.
For most of you this shouldn't matter at all. Most of you readers have never attended the complexity conference (though you ought to give it a try sometime) and those that do would probably continue attending no matter who sponsors the meeting.

There has been a go-it-yourself tendency in this field so as not to pay any organization fees and to publish papers in an open-access format. Just realize this approach has some potential downfalls.
  • Without a sponsor, the conference and in particular the organizing committee, is fully responsible for any deficit. One bad hotel contract can sink a conference. To guard against this, you'll need to budget a surplus far larger than IEEE or ACM would require. Also IEEE and ACM can use their influence to get better deals such as on hotels. 
  • You'll need considerably more volunteer time from faculty to handle the larger administrative load. This time doesn't show up in the financial calculation but it is a real expense.
  • Having a sponsoring organization gives a set of checks and balances to guarantee that the conference retains a consistent mission and be fiscally responsible. If a conference is solo and the organizing committee drops the ball, the conference just disappears. 
I'm not recommendation here, just trying to point out some pitfalls that usually don't get discussed. I'll stay out of the actual debate on the future sponsorship of CCC and leave that to the younger generation.

Sunday, February 09, 2014

Superbowl underdogs and overdogs

(Stephen Colbert tells me that NFL guards their copyright of the name of the game they played on Sunday, which is why stores say they have a `big game sale on beer'. I will get around this the same way he does. I hope he doesn't sue.)

In Superb owl XLVIII (48) (one of the few uses of Roman Numerals left) Denver was the favorite but got beaten. This is not so unusual and they were not a favorite by much-just 2.5 points. But they lost 43-8. That sounds unusual--- for the favorite to get completely whomped (spellcheck thinks that's not a word, but spellcheck doesn't even think spellcheck is a word).

So- how uncommon is it for the favorite to get whomped? We would need a rigorous definition of whomped. I'll say two touchdowns, or 14 points. A list of all of the superb owl games and what the spread was and what happened is here. I summarize:

  1. The underdog WON 15 times. The most surprising was probably when the NY Jets were an 18-point underdog to the Baltimore Colts  in Supeb owl III in 1969 and won 16-7. Good thing they won since Joe Namath (the NY Jets QB) guaranteed  victory.
  2. In 2010, Superb owl 44,  Indianapolis was a 5 points favorite over the New Orleans Saints but the Saints whomped  31-17.
  3. In 2003, Superb owl 37,  Tampa Bay was a 4 point underdog to Oakland. Tampa Bay whomped by winning 48-21.'
  4. In 1988, Supeb owl 22, Washington was a 3 point underdog to Denver, but Washington whomped 42-10.
  5. In 1984, Superb owl 18, LA was a 3-point underdog to Washington, but LA whomped 38-9.
  6. In 1981, Superb owl 15, Oakland was a 3 point underdog to Philadelphia, but Oakland Whomped 27-10.
  7. In 1970, Superb owl 4, Kansas City was a 12 point underdog to Minnesoda, but whomped 23-7.  The reason they were an underdog is that people still though the AFC to be the lesser league and didn't remember that in Superb Owl 3 the AFC won (though didn't whomp).
So the underdog has whomped 5 times. That is FAR MORE than I would have thought. Does this show that underdogs are undervalued? Not sure since if an underdog wins it doesn't matter by how much for the betting, where as if a favorite wins it matters by how much for the point spread.

This may also call into question if point-spread is the best way to express `this teams is that much better than that team'. One issue (though it was NOT an issue in Superb owl 48) is that if a team is behind
then they may use a high-risk high-reward strategy which, if it fails, they lose my a lot. The phrase one may hear is ``the game was closer than the score''.  Note that for baseball they don't do point spreads, they do odds instead. Should Football follow that? What are the PROS and CONS of points spread vs odds?

The cliche is `I watch the game for the commercials' I actually skip the game and watch the `best of superb owl commercials' that come the week before the game.

Thursday, February 06, 2014

Favorite Theorems: Connecting in Log Space

We start the favorite theorems with a result that might surprise many is still less than ten years old.


Intuitively, this result says you can tell if two points are connected in a complex maze by only having to remember the equivalent of a constant number of locations in the maze. Reingold's algorithm builds an expander graph based on the zig-zag construction in a very clever way that uses very little space to construct and to check that two points connect.

In 1979, Aleliunas, Karp, Lipton, Lovász and Rackoff showed that one can solve s-t connectivity in randomized logarithmic space by taking a random walk on the graph. My last favorite theorem from 2004 talked about derandomizing space algorithms and before Reingold the best algorithm for s-t connectivity required log4/3 space. Indepently of Reingold, Vladimir Trifonov gave a O(log n log log n) space algorithm for s-t connectivity, a victim of bad timing.

One neat implication of Reingold's result is a new and simpler characterization of log-space as the set of problems expressible in first-order logic with ordering and symmetric transitive closure.

After Reingold's result we might have expected solutions to a number of related problems but we didn't see much progress.
  • Can every randomized log-space algorithm be derandomized in log space?
  • Do there exist log-space computable universal traversal sequences? 
  • Can we solve directed s-t connectivity better than Savitch? 
  • Can we modify Reingold's algorithm to bring log space into NC1?

Monday, February 03, 2014

Contribute to the Martin Gardner Centennial

Dana Richards emailed us about a place to write how Martin Gardner influenced you. You can leave such comments here.  I left a comment there, but I expand it for this blog entry.

When I got interested in mathematics in high school I went to the public library looking for math books (this was before Al Gore invented the internet). I found some books by Martin Gardner and began reading them. They were just right for the level of math I was on at the time. My very first proof that I read on my own (outside of a class) was in those books- the proof that (in the terminology I use now) a graph is Eulerian iff every vertex has even degree.

I  learned about SOMA cubes (I bought a set and did every puzzle in the book in about 2 days.This is the only evidence that as a kid I was good at math). I learned the unexpected hanging paradox which confused me then (and still does). I learned the hercules-hydra game and other games that go on for a LOOOOOOOOOONG time. They are related to things in logic. I also learned about NIM games which I have used as a starting point for several student projects.

There have been some conferences in his honors, the Gathering-for-Gardner. I had the pleasure of reviewing some of the books from it. (My review is here.) These articles show that while his work was recreational this is not a well defined term- some if relates to very important and deep mathematics, and some deep math has arisen from such problems. The books also have articles about Gardner the Magician.

In  the 2000's some of his books were reprinted and I was asked to review them for my SIGACT News book review column.  I took this opp to do a joint review of several math recreational books. What a delight to reread his books and contrast them to those of his successors. And I STILL learned some math that I didn't know from them. (My review is here.)

Shortly before a column appears I always email the authors-of-books, authors-of-reviews, and publishers a first draft of my column. His publisher told me that he didn't use email (he was in his 90's!) so I postal mailed him my review. He read it, corrected some typos, but otherwise was quite happy with the review. He died a few months later. I was happy to have some contact, albeit short, with the man who helped keep me interested in math in high school and beyond.

Wednesday, January 29, 2014

Snow Days

An unexpected snowstorm hits the city in the middle of a workday. The roads get hopelessly clogged and I'm lucky to get home--many others just abandoned their cars, or slept in them. I'm talking about Valentine's Day, February 14, 1990 in Chicago. But the same story hit Atlanta yesterday. One big difference--Georgia Tech is closed today and tomorrow because the city can't handle the ice. The University of Chicago was open on February 15th. 

When these events happen, people wonder about the planning. Was it wise for all schools and businesses to shut down about the same time, early yesterday afternoon? Lots of blame to go around (and having CNN based in Atlanta guarantees coverage) but it is not clear that any plan would have done much better--how do you get millions of people safely home with dangerous roads and a limited public transit system? One of these times you wish P = NP and you can just find the right algorithm. One of the issues is that freak mid-day snowstorms don't happen that often, the last major one in Atlanta was 1982.

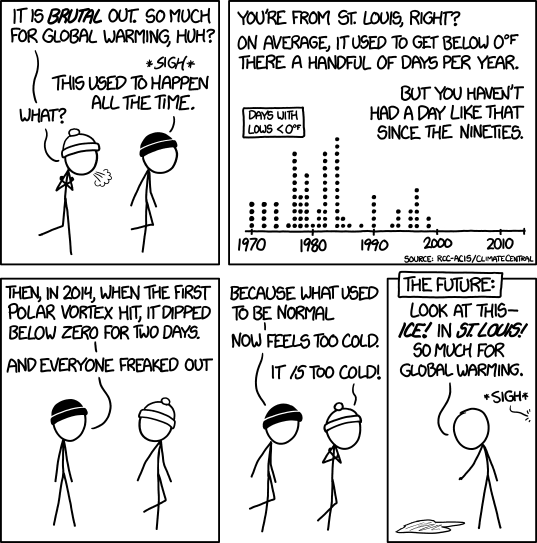
Meanwhile back in Chicago, schools were closed earlier this week, not for snow but for cold. But it was that cold on a regular basis back in the 90's. Global warming has changed expectations, as so brilliantly illustrated in this xkcd. 


Monday, January 27, 2014

Fermat's Last Theorem and Large Cardinals. Really!


A brilliant math ugrad at UMCP, Doug, is also a creative writer who
wants to work on large cardinals. His creative writing may help him there.
We had the following conversation:

DOUG: The proof of Fermat's last theorem depends on the existence
of certain large cardinals and hence is not in ZFC.

BILL: That is not true.
DOUG: Have you read the proof?
BILL: No, however, if that were true I would know it. See this blog entry.
DOUG: Why would you know it?
BILL: If FLT required LCs then

a) Number theorists would be nervous.
b) Logicians would be ecstatic
c) The math community would not have announced to the world that FLT was solved.
d) Wiles would not have collected his prize money for solving it.
e) Again, I would know it.

DOUG: All compelling arguments. Even so, FLT requires LCs.
BILL: I will bet you five dollars that the current proof of FLT does not depend on LCs.
DOUG: Uh. Your counter arguments are compelling.
BILL: So... no bet?
DOUG: Uh. No.

The next day I got an email from Doug with the subject heading

        I cheated myself out of five dollars.

 Doug found this article, What does it take to prove Fermat's Last Theorem? Grothendieck and the logic of number theory by Colin McLarty, from 2009.The article says that YES the  current proof of FLT DOES depend on LCs. Note that the proof is quite long and uses lots of other stuff that is sort of buried in it. So--- whats the catch?Why aren't number theorists nervous and logicians ecstatic? According to the article anyone who reads the proof of FLT and wanted to could unwind it  and get it down to ZFC (and likely down to PA). But nobody has bothered yet.Hence nobody is nervous or ecstatic.

I will take their word for it, but it does make ME nervous. NOT about FLT which I am sure enough people have looked at (and looked at the background literature) that it really can be made to work in ZFC.I am more worried about papers that are not quite so looked at as having LC assumptions that are hidden from the reader that cannot be easily removed.

However KUDOS to Doug for telling me something in math that I did not know and should have.  I will treat him to a more-than-five-dollar-lunch.

Postscript: AH, the article was right: FLT was proven using ordinary set theory last year. (See here) by Colin McLarty (I assume its the same person). I will still take Doug to lunch- in a stupid, pedantic, technical sense I was right- the current (2014) proof of FLT did not use LC. But for the real issue of there being any problem at all, I was clearly wrong. Only a logician would say I was right. Hmm- Doug is a logician. Its up to him. (Hmm- my spell checker allows `Hmm' but not `Hmmm')

Thursday, January 23, 2014

What will we wrought?

When I went to college in the early 80's, students protested against college endowments invested in companies that had business in apartheid South Africa. My mother worked as a statistician for one of those companies. An interesting dilemma, do I support a policy that hurts the company that is indirectly helping to put me through college?

Now my daughter is in college and worrying that the computing revolution will make it hard to find a job once she graduates and making her consider those job prospects in the major she chooses. And what am I? Chair of a computer science department that helps push that revolution forward.

Computing gets quite a bit of blame these days for the widening income gap between the have and the have nots, and jobs taken over by automation, but without causing a corresponding need for other types of jobs, other than those that serve computation itself. Are those fears real? We can't answer that question yet, positively or negatively. Time will tell.

For now, we just need to do our jobs, making computing better but also understanding and mitigating the negative effects of computing. We need to make sure that computing technology becomes a growing sea that raises all boats, and not just making the world better for the technological elite.

While I stand in awe in how computer science has changed the world, I hope we don't ever end up with CS leaders getting together and saying "What have we wrought?"

Monday, January 20, 2014

We don't care about Ballroom Dancing. Should we?

YOU got into your undergrad school because not only were you good at Math but you were on
the Fencing Team and in the Latin Club (so you could taunt your opponents in Latin: ouyah allcay athay an alestrabay!). Also you had a letter from your principal who never had you for a class but can comment on your leadership since you organized a pep rally for the football team. Why does UNDERGRAD admissions care about these things? Because, while they want good students, they also want to build a community of scholars of different interests and abilities.

YOU apply to grad school in Computer Science. Hey, it worked once maybe it will work again! You write about being in the ballroom dancing club and you have a letter from the Dean, who never had you in a class,
but you worked in his office and he can attest that you are a good leader and a hard worker.

Does the admissions committee care? NO. The only things we care about are CS, MATH, and RESEARCH. A letter from someone not in math or science is worthless. Some exceptions and thoughts:

  1. If you recorded ballroom dancing and made a project out of how to teach it using some interesting new technology this IS good. This is likely an Human-computer-interaction project; however, I would care about this no matter what field you are going into.
  2. If you have an interest in Nat Lang Proc and know Linguistics I would care.  I would think that knowing a foreign language would also be good.
  3. If you are going to go into Human computer Interaction then Psychology helps.
  4. If you are going to do Quantum Computing then Physics is good. However, whatever you do Physics is good as its more evidence of math ability.
  5. For ugrad its been said that if your parents are powerful OR donors you may have an easier time getting into some UGRAD schools. What about Grad school? I've honestly never seen a case of this so I honestly don't know. 

I know a student who is an excellent math major but also a creative writer. I doubt this will help him.
but should it?

I once saw in a students application a letter from his preacher attesting to his fine moral character.
Do we care? should we? How about the other way around- if someone was an EXCELLENT programmer and math person but served 8 years for armed robbery would we care? This might not be fair since perhaps he reformed.

but my real question is- for grad admissions we don't care about Ballroom Dancing or other misc.
Is this a mistake? If someone was NOT as good at math BUT a better writer, should we take them?

Thursday, January 16, 2014

Favorite Theorems: Introduction

I was invited to give a talk at the FST&TCS conference held in December 1994 in Madras (now Chennai). As I searched for a topic, I realized I was just finishing up my first decade as a computational complexity theorist so I decided to recap the past decade by listing My favorite ten complexity theorems of the past decade (PDF). Not so much to choose winners, but use the theorems to survey the great research during those past ten years.

In 2004, I repeated the exercise in my then young blog for the years 1995-2004. In 2005, I went back in time and chose my favorite theorems from the first decade of complexity (1965-1974) and in 2006 I covered 1975-1984, completing the backlog of the entire history of computational complexity.

Now in 2014 we start again, recapping my favorite theorems from 2005-2014, one a month from February through November with a recap in December. These theorems are chosen by a committee of one, a reward only worth the paper they are not written on. I choose theorems not primarily for technical depth, but because they change the way we think about complexity. I purposely choose theorems with breadth in mind, using each theorem to talk about the progress of a certain area in complexity. I hope you'll be presently surprised by progress we've made in complexity over the past decade.

Tuesday, January 14, 2014

A short History of Crypto

I taught a 3-week summer course to High School Students called

Computer Science: A Hands Off Approach

which did some theory. One thing I did was the following storyline:

  1. Shift Cipher
  2. Affine Cipher
  3. Gen perm cipher (any perm of a,b,c,...,z
  4. PROOF that perm is unbreakable: Eve has to go through all 26! possibilities
  5. PROOF that perm IS breakable: Freq analysis. Moral of the story: Any proof that a system is unbreakable makes some assumptions that Eve might not agree to. Hence proving security is tricky.
  6. Matrix Ciphers. PROOF that if you use a big enough matrix its unbreakable. Sort-of true for ciphertext only (though I doubt really proven). PROOF that requires going through all possibile nxn matrices that have det rel prime to 26 to crack it using plaintext only. PROOF that this is NOT true (I leave that to my reader).
  7. Vig Cipher. Proof that its unbreakble, Proof that you can break it
I was very happy with this since it really instilled in them that proofs of security are nontrivial and always have assumptions. That does not mean they are not worth anything, but you want to get the assumptions explicit to if (or even WHEN) the system is broken, you can see what assumption needs to be attended to for the next iteration. One caution- these were VERY GOOD students so they GOT IT. They didn't mistake the false proofs for real ones.
(NOTE-- I never teach the cows paradox - all cows are the same color- when
doing induction since half the class will think induction can prove anything and the other half will think that all cows are the same color.)

I then encapsulated all of this with what I call A SHORT HISTORY OF CRYPTO:

 For i=1 to infinity
                Alice and Bob: We have a cipher that nobody can crack
                Alice and Bob: We have PROVEN that it can't be cracked
                Eve: I just cracked it
                Alice and Bob: Whoops.


(I later did Diffie-Hellman in the class which I will talk about in a later blog.)

Thursday, January 09, 2014

Is Traveling Salesman NP-Complete?

[Nina Balcan asked me to mention that the COLT submission deadline is February 7]

Jean Francois Puget writes a controversial post No, The TSP Isn't NP Complete which I discovered during a lengthy twitter discussion with Puget and Peter Cacioppi.

There is a well-known technicality for the Euclidean Traveling Salesman problem but let's focus instead where we are given a complete graph weighted with positive integers. One version of TSP is truly NP-complete
TSP Decision: Given an integer B, is there a cycle through all the vertices such that the total weight of the edges used is at most B?
TSP Decision is in NP by guessing the cycle and hardness by a simple reduction from Hamiltonian Cycle.

Puget's makes the point that we normally think of the TSP problem as an optimization question
TSP Minimization: Find the cycle through all the vertices that minimizes the total weight used.
TSP Minimization is not even a decision problem. In the 80's, Mark Krentel created a complexity class OptP to capture optimization problems and showed that TSP Minimization is Opt-P-complete.

One can use TSP Decision to solve TSP minimization by doing binary search, so they have effectively have the same complexity.

Puget points out that even if we are given a tour, checking that it is the shortest tour is not believed to be in NP. That problem is in co-NP and I'm guessing co-NP-complete. [Update 3/20: I was right]

Puget doesn't like when people claim TSP is NP-complete when they are talking about the optimization problem. For example from my P v NP survey
The NP-complete traveling salesperson problem asks for the smallest distance tour through a set of specified cities. 
I'm far less bothered than Puget. Those who understand the technicalities of NP-completeness know that one has to convert the optimization problem to an appropriate decision problem to formally get an NP-complete set. Others aren't led too far astray, for we do have an equivalence that P = NP if and only if there is an efficient (polynomial-time) algorithm for TSP Minimization.

Monday, January 06, 2014

Tell me more about Alice and Bob

A while back my parents were in town on a weekend when I was scheduled to give a talk to HS students who had done well on the Maryland math competition. Logistics dictated that my parents goto the talk. (They were both English majors and wouldn't like me using the word `goto' since its not a word. Fortunately they don't read this blog and see what else I do to the English Lang.)
I gave a talk on Communication Complexity (slides are here) where I did the following:

  1. I stated the problem: Alice has x, Bob has y, both strings of length n. They want to know if x=y without too much communication.
  2. I noted that they can easily solve this with n+1 bits of communication and raised the question of Can They Do Better?
  3. We discussed this. Someone mentioned average case (informally), which helped me clarify the problem. Someone else suggested sending the number-of-1's and if it didn't match they weren't equal, but also noted that if they did--- weren't sure. Most thought that one COULD do better or else I wouldn't be talking about it.
  4. I tell them that NO you can't do better (I do not prove this).
  5. I told them about mod arithmetic and how in mod p, p a prime, poly of degree d have at most d roots.
  6. I presented the O(log n), error 1/n, randomized protocol for equality that uses polynomials mod p.
  7. I briefly talked about comm complexity in general.
The talk went well. It is a good topic for good HS students, and if you want to borrow my slides you can (you may need to update the political reference). Having not understood ANY of the talk Mom had the following question:
MOM: Alice and Bob-- are they married?
BILL: Oh. I'll say no.
MOM: If they are not married then how come they have such a hard time communicating?
DAD: (he didn't say anything but I could tell he agreed).


Thursday, January 02, 2014

Two cheers for the Pardon of Turing. But not three.


As I am sure readers of this blog know Alan Turing was prosecuted for homosexuality in 1952, forced into hormone treatment, and committed suicide in 1954 (I had always heard that that was WHY he committed suicide
though the dates don't quite line up--- at that time he seemed to be recovered form the ordeal. So there are some legit questions about this.)

He was recently given a Royal Pardon. While I am glad he was pardoned this does raise some questions. Lets me logical.

  1. If we believe the law criminalizing homosexual acts was unjust (as I am sure that all of my readers do) then Turing is a red herring- they should pardon ALL people convicted. AND note that  according to this there are 15,000 men who were convicted of this crime who are still alive.
  2. Pardon means that the person didn't do the crime. This is not the case here. However, laws are supposed to promote justice, not block it.
Here is hoping that the Pardon of Turing will lead to a general pardon.

(NOTE- the pointer in item 1 says more of what I wanted to say, but says it
more elegantly than I ever could.)

Monday, December 30, 2013

2013 Complexity Year in Review

The complexity result of the year goes to The Matching Polytope has Exponential Extension Complexity by Thomas Rothvoss. Last year's paper of the year showed that the Traveling Salesman Problem cannot have a subexponential-size linear program formulation. If one could show that every problem in P has a short polynomial-size LP formulation then we would have a separation of P and NP. Rothvoss' paper shoots down that approach by giving an exponential lower bound for the polynomial-time computable matching problem. This story is reminiscent of the exponential monotone circuit lower bounds first for clique then matching in the 1980's.

If you expand to all of mathematics, one cannot ignore Yitang Zhang's work showing the liminf of the difference between consecutive primes is a constant. Dick and Ken have other great results for the year.

A big year for theoretical computer science. Silvio Micali and Shafi Goldwasser received the ACM Turing Award. The P v NP problem makes a prominent appearance on a major US television series. We are seeing the rise of currencies based on complexity. Large-scale algorithms, cryptography and privacy play center stage in the Snowden revelations on the National Security Agency.

Generally good news on the funding and jobs front in the US. After a year of sequestration and a government shutdown, looks like some stability for science funding now that congress has actually passed a budget. Plenty of theorists got academic jobs last spring and given the number of ads, this year's CS job market should be quite robust as well.

A year for books. Of course my own Golden Ticket as well as Scott Aaronson's Democritus and Tom Cormen's Algorithms Unlocked.

An odd year for the blog in 2013 without a single obituary post. Nevertheless let us remember 4-Colorer Kenneth Appel, Georgia Tech Software Engineering Professor Mary Jean Harrold and Wenqi Huang who led the Institute of Theoretical Computer Sciences at the Huazhong University of Science and Technology. In 2013 we also said goodbye to Alta Vista, Intrade, Google Reader and the CS GRE.

In 2014 we'll have the next installment of My Favorite Ten Complexity Theorems of the Past Decade and the centenaries of George Dantzig and Martin Gardner. Enjoy New Years and keep reading.

Thursday, December 26, 2013

To Write, or Not to Write, That Is the Question

Guest post by Vijay Vazirani

Our field has been blessed with some great books: classics such as Knuth's volumes and Garey & Johnson literally got the field going, and the books of Lovász brought much clarity in difficult, important areas. The new millennium brought a plethora of new books by famous TCS researchers including Arora, Barack, Goldreich, Kleinberg, Nisan and Tardos. With an astonishing 33 short titles in theory, Now Publishers has virtually created an assembly line for producing books.

Even so, when faced with the prospect of writing a new book, I am filled with trepidation and self-doubt: Am I up to the effort needed? Do I have a genuinely new point of view to expound? If so, have I figured out the "right'' format and style for expounding it in the simplest and clearest manner?

The issue arose when I decided to co-teach, with my able postdoc Ruta Mehta, the course Equilibrium Computation in Spring. With her characteristic enthusiasm, Ruta has practically forced me into a long-term commitment of writing a book on this topic. However, knowing what it takes, so far I have managed to resist an unequivocal "yes".

Most people would say it is a losing proposition -- the gains are typically minuscule compared to the toils. So why do so many people write books? I can imagine several reasons, but best to leave this discussion to my esteemed colleagues who are probably yearning for something to ponder on in this holiday season ...

That brings me to another question, "Are some of the books written in this millennium eventually going to be regarded as classics in the style of Knuth or Lovász's books?'' One could look at citation counts or average citations per year to get an "objective'' reading of the situation. However, when one is talking about true class, such crude estimators are clearly not the way to go.

Your thoughts are eagerly sought ...

Monday, December 23, 2013

Our Journal is 99 44/100 percent pure!!

Sometimes we are asked to evaluate how good a journal or conference  formally(Excellent, Very Good, Good, Fair, Better-than-being-poked-by-a-stick,pass the stick). Sometimes we talk about these things informally (ICALP is the European STOC! SODA is as hard to get into as FOCS!, CCC is a topTier topics-conference!)


But is there a way to judge these things formally? And should there be?Be aware of Goodhart's Law:

When a measure becomes a target, it ceases to be a good measure.
 One way to measure how good a journal or conference is  impact factor which is based on number-of-citations. Does this work well? Some issues:
  1. Even with an honest effort these things are hard to do well. People may cite the conference version, the journal version, the arXiv version, or just give a website.
  2. Even with an honest effort just a few articles can skew the results.
  3. Its hard to compare cross-fields.  I suspect that pure math journals have lower citations rates than biology journals.
  4. If an author cites himself, should that count?
  5. The above points were all about HONEST efforts. Could a journal do things to boost its impact factor and then brag about how high their impact factor is? Would they? Alas yes, see this article and this article.
So what are we left with? We could just go on our gut, but that favors journals that used to be good and aren't any longer. But the problem is deeper than all that--- can't we just say Thats a good article  and not have to proof it by saying where it was published? Alas no- all fields have gotten specialized that we must use these proxies to inform us.

 I COULD rant that we should all be well rounded enough to read outside of our field, but I know how hard that is.

I COULD rant about the dishonesty pointed out in the above links, but that's only part of the problem.

I COULD say What do you think? so I will.

Thursday, December 19, 2013

Security Changes

A couple of policy changes recently, one that supposedly enhances privacy and another that could reduce it.

Google has been implementing perfect forward secrecy since 2011 and other major Internet players, such as Facebook and Twitter, have started using perfect forward secrecy in the wake of the Snowden revelations that the NSA has been collecting Internet traffic to these companies.

So what is perfect forward secrecy? Not an easy question to find the answer to on the Internet. The wikipedia article says little. So I asked a couple of our security folks in the department.

The rough idea: We want to communicate several rounds of messages but if the current keys are compromised they can't be used to decrypt earlier messages. A couple of immediate thoughts: This isn't "perfect", you can still discover the earlier messages by breaking the encryption (say if P = NP). Also this isn't that exciting a problem from a theoretical perspective, you can just use a standard public-key protocol and start with fresh private and public keys each round and deleting the old ones. But that isn't very efficient.

One approach to PFS: Have a standard public/private key scheme to set up a session key (used in an AES or similar private key protocol) then run separate Diffie-Hellman schemes for each message. In RSA if you have the factors for N you can decrypt, where in Diffie-Hellman you can keep the same group without compromising security.

Chris Peikert calls this a poor-man's perfect forward security and there are better schemes though a bit more complicated.

On a different front, Google recently announced that images by default would be displayed in gmail messages. The images would not come directly from the sender, which could contain malware that avoids Google's filters, but rather from Google's servers after being downloaded and cleansed by Google.

Downloading an image often tells the sender that the image was read, typically with some id encoded in the filename. So once again we give up privacy for convenience. At least Google gives us the option to turn off the automated displaying.

Monday, December 16, 2013

Analogs between Quantum Computing and Parallelism

(Jon Katz wanted me to mention this:  A wise man once noted that there are fewer quantum algorithms than thereare quantum-algorithms textbooks! But there is still a lot of interest inquantum computation from cademia,government, industry, and the broader public. Univ of MD and NIST have recently formed a
center devoted to quantum computing and involving faculty and researchers from both physics and computer science communities. As part of this they are advertising a posdoctoral fellowship.)

A long time ago people in theory did  a lot of work on parallel computing before
there were many parallel computers build. Today people are doing a lot of work on quantum computing before quantum computers are build. What is similar and different here?

  1.  When parallel computers were actually built they were not like PRAM's. Many of the models assumed shared memory which wasn't true. Even so, did the work on PRAMS and other models help the practioners? Directly? Indirectly?
  2. Are the models of quantum computing studied now helping the practioners? Is the development of quantum computers at too early a stage to even ask this question?
  3. Even if no quantum computers are ever built the study has been a sucess since some classical problems have been solved using quantum techniques (and I think this will happen more and more). And some interesting math has come out of it. And physicists and others have learned more about quantum mechanics from quantum computing. Could the same thing have been said for parallelism- even if parallel computers had not been built would the study of them have still be useful?
  4. One big difference- many problems can be parallelized in some form and solved that way (and some cannot be solved any other way). A wise man named Jon Katz referred above to a wise man named Ronald de Wolf  who wrote, in a review of 3 books on quanum computing:

 A quick survey on amazon.com shows that the number of books on quantum computing (at least 20) is more than 10 times as high as the number of quantum algorithms (2: Shor's and Grover's). (Footnote: Note that this review was written in 2003 so this statement is no longer true.)

While  I think he meant there are more quantum algorithms (quantum random walks, quantum simulations, quantum selection-type problems?, quantum number-theory-type-problems?) now than in 2003, I will note that there are also more books on quantum computing now than then- on a cursory look at amazon I think I counted 30, but with the uncertainly principle, its hard to tell.  The point is, aside from factoring and of course quantum simulation I wonder if when  quantum computers, if they are build, will be able to do much more
BUT SEE NEXT PARAGRAPH. (Every year my students are surprised to find out that quantum computers probably CANNOT solve SAT in poly time.)

ADDED LATER: Comment 6 has a pointer to a survey of MANY quantum algorithms for MANY algebraic problems, and also a pointer to a more recent article on quantum algorithms. I will be delighted if the number of quantum algorithms now exceeds the number of books on quantum computing.

Thursday, December 12, 2013

Approximate Computing

Hadi Esmaeilzadeh is the newest professor in the School of Computer Science at Georgia Tech. Hadi works in computer architecture and did some great work on dark silicon. (Just noticed this is starting to look like a Lipton-style blog post.)

I had Hadi give a lecture in my theory class (the dreaded day-before-Thanksgiving lecture). Hadi talked about his new research directions in approximate computing. Approximate computing is a new paradigm in the architecture community, doesn't even have its own wikipedia entry yet.

When you do arithmetic operations, say addition and multiplication on real numbers, you typically want full precision up to the limits of the bits we use to store those numbers. Suppose you allow some error, say 5%. For logical operations, this would be a disaster giving a very wrong answer. Running various optimization algorithms, like simplex, these error might compound leading to very suboptimal results.

But there are several scenarios where approximate computing might not hurt that much. Processing media, like pictures, sound and video, are not exact anyway and a small error might not degrade the quality successfully. Statistical methods that sample a large space, such as when we analyze big data, still could yield reasonable results using approximate computing.

Why do approximate computing? Because of the architecture--approximate computing can be done often faster and with less power consumption. The tradeoffs may allow approximate computing to handle tasks beyond what we can do with traditional computing.

Approximate computing needs good theoretical models and that's where our community can come it. What's the right way to model the power-speed-accuracy tradeoffs and how can we determine the right computational problems that can take advantage of these tradeoffs. Might have nice connections to learning theory and property testing.

Monday, December 09, 2013

Inventions are Non-Commutative: Amazon vs Amazon

(Tal Rabin, Shubhangi Saraf and Lisa Zhang asked me to remind you to publicize this: the bi-annual Women in theory (WIT workshop), NYC, May 28-30, 2014. Apps due Jan 20, 2014. Go here for all relevant information)

If FAX machines had come out 20 years earlier they would have had far MORE impact.
If FAX machines had come out 20 years later they would have had NO impact since by then
we all had email and scanners and what not. So when an invention comes out matters.

Ask your grandparents what white-out was for corrections on a typewriter (while you are at it ask your grandparents what a typewriter is). If it came out 20 years later then Bette Nesmith  would have not made 50 million dollars, her son Michael Nesmith would not have had the spare time to become a musician and there might not be a group  called THE MONKEES. Gee, we would have no LAST TRAIN TO CLARKSVILLE. But I digress (from what?).

If Lasik  eye surgery came first and glasses later, glasses may have been seen as a great way to avoid surgery!

Amazon is working on a technology that may become obsolete before it really takes off. I am referring to the Amazon Drone Project. The idea is that when your order an item from Amazon a drone will get it to your house (or perhaps wherever you are) VERY FAST - maybe within 30 minutes. This works well for objects under 5 pounds. Say like what Amazon is best know for BOOKS.

But there is an a technology out there that may kill this idea before it gets off the ground. There is a competing company called Amazon which has already developed ways for people to get books on what they call a Kindle, which is like emailing them a book. So there is NO Physical object to be delivered.
Hence the Amazon Drone project may, like the 8-track tape (ask your great grandparents) become obsolete due to technology being developed by Amazon.

I wonder- had Amazon Drone come out 20 years ago would it have had more impact? Would it have made less of a demand for Amazon Kindle?

Amazon Drone may still have an impact by delivering other things. But I wonder how long it will take before 3-d printers make MOST things that Amazon delivers not need to be physical objects.

Thursday, December 05, 2013

Bitcoins Revisited

Two years ago I gave a lecture and posted about bitcoin. Of course what I didn't do was buy a bitcoin whose value back then was about $3 and today runs in the $1000 range.

Bitcoins have received quite a bit of press, particularly with the FBI shutting down Silk Road, the drug trafficking site which used bitcoins for their transactions. Then people realized that bitcoins are starting to become a real currency, with a market cap of about US$11 billion not far now from the money supply of the Costa Rica Colones (US$13 billion). Now governments are deciding on how to deal with bitcoins as a currency, one which they really can't regulate or control.

The Economist has one of the better articles on Bitcoins, talking about some of the technical issues involved.
The Bitcoin system is designed to cope with the fact that improvements in computer hardware make it cheaper and faster to perform the mathematical operations, known as hashes, involved in mining. Every 2,016 blocks, or roughly every two weeks, the system calculates how long it would take for blocks to be created at precisely 10-minute intervals, and resets a difficulty factor in the calculation accordingly. As equipment gets faster, in short, mining gets harder. But faster equipment is constantly coming online, reducing the potential rewards for other miners unless they, too, buy more kit. Miners have formed groups that pool processing power and parcel out the ensuing rewards. Once done with ordinary computers, mining shifted to graphics-processing units, which can perform some calculations more efficiently. Miners then moved on to flexible chips that can be configured for particular tasks, called field-programmable gate arrays. In the past year, bespoke chips called ASICs (application-specific integrated circuits) have appeared on the scene.
Then there was the paper Dorit Ron and Adi Shamir wrote that explored the bitcoin transaction graph and suggested a (now supposedly debunked) connection between the mysterious creator of bitcoins, "Santoshi Nakamoto", and Ross William Ulbricht aka Dread Pirate Roberts, the founder of Silk Road.

Bitcoins even make it to my Thanksgiving table. My brother thought they were a scam even though I pointed out the systems has no scammers. He remains unconvinced though he invests heavily in gold, which has the same property of the value mostly being there because people believe it has value.

I taught a lecture on bitcoins again in my intro theory course. We all generally agreed that a few years from now we'll all remember the days when bitcoins were worth $1000. Not sure we'll remember those days because bitcoins will be worth millions or because they'll be worth pennies.

Monday, December 02, 2013

Global Warming and the Axiom of Choice

Who was the first scientist to warn of Global Warning? These questions are complicated, but I would say it was Bing Crosby in a paper called White Christmas. Here are the first two lines:
I'm dreaming of a white christmas
Just like the ones I used to know
Why are there no more white christmas's? Because global warming made it stop snowing!

Why do otherwise intelligent people refuse to believe that Global Warming is real and is caused by humans and we we need to do something about it? I have a conjecture and an analog. Here is what I think the reasoning is

  1. Republicans have the following AXIOM (until they are in office): government IS the problem, not the solution. More than this, they think that there is NO problem that requires government action.
  2. Consequence: Government should do NOTHING about Global Warming.
  3. Since Government shouldn't do anything about Global Warming, it is not a problem.
Rather than rethink their AXIOM they accept the conclusion that Global Warming is either not a problem or not caused by humans. The shame of it is that there ARE economically viable ways, perhaps moderate republican ways, to fight global warming- some version of Cap-and-trade, or pay-to-pollute. And getting off of Fossil Fuels would be good for other reasons. I can picture history going a different way so that Republicans want more fuel-eff cars to get us off of Mideast Oil. I can picture a history where the insurance companies are more powerful than the oil companies for lobbying and hence Government takes LOTS of action against global warming.

Are their things in math where people accept an axiom despite its absurd consequences?Yes:
  1. Most math people believe the Axiom of Choice.
  2. Consequence: the Banach-Tarski Paradox

Rather than rethink their AXIOM they accept the absurd conclusion that you can break a ball into 5 pieces, reassemble, and get twice the volume. Fortunately, believing this does not endanger the planet.

Monday, November 25, 2013

The Institute for proving Graph Isomorphism is in P


(This post was inspired by Adam Winklers awesome book
Gunfight: The Battle over the Right to Bear Arms in America.
Disclaimers one: Adam Winkler is my cousin and I got a free copy.
Question: Should I give him a free copy of my VDW book when it comes out?
Disclaimer two: Scott did a post on a related matter here.)

If someone started an Institute to prove Graph Isomorphism is in P that would
be very odd since it could be that GI is not in P.
If someone started an Institute to study Graph Isomorphism that would be
much less odd (though still somewhat odd).

Does it make sense to have an openly biased think tank?

  1. If a pro-gun-control person writes a book that proves that there weren't that many
    guns in America in the early 1800's would you believe it?
  2. If an anti-gun-control person writes a book claming that the more guns there are
    the less crime there is, would you believe it?
  3. The CATO Institute: A Libertarian Think Tank.
    If they did an honest study of gun control and concluded that it does reduce
    crime then would they publish it? I honestly do not know.
    If they did an honest study of gun control and concluded that it increases
    crime then would anyone believe it? Being openly biased might undermine their credibility.
  4. The Tobacco Institute (they no longer exist). They produced reports
    claiming that smoking was not unhealthy (or perhaps that the evidence is incomplete).
    They were employed by the Tobacco industry. Did they ever have any credibility?
    Did they do any unbiased science, perhaps on non-smoking issues?
    I honestly don't know.
It is tempting to say Scientists should not have an opinion before they do a study. But this is clearly not correct in theory or practice. Scientists do indeed have an opinion, even an interest, in what a study will tell. Why is that different from the Tobacco institute?
  1. An honest scientist's preconceived notions are hopefully also based on science and not on who is paying him and not on other non-science factors.
  2. An honest scientist, when faced with evidence that they are wrong, will hopefully pursue that evidence and perhaps change their mind. This might be easier in math than in science since Proof is our accepted criteria. For example, I doubt there are diehards who still think that NL ≠ coNL.

Tuesday, November 19, 2013

The New Patrons

A few centuries ago if you wanted to do science and not independently wealthy you needed help.
Most of the important astronomers and natural philosophers (as well as artists) in the 16th and 17th centuries depended on the patronage of powerful religious or political figures to fund their work. Patronage networks extended all the way from Emperors and Popes to regional nobles to artisans to peasants; even university positions were based to some extent on patronage. Scholarly careers in this period were driven by patronage, often starting in undistinguished universities or local schools or courts, and traveling closer or farther from centers of power as their fortunes rose and fell.
Today most scientists have salaried positions at universities and get funded by the government but with sequestration and budget cuts, scientists have to seek out other sources, such as industrial funds. We've long had various scholarships endowed by private donors: Sloan, Packard, MacArthur. Recently though we've seen some new patrons, the upper 1%, who want to help out where other funds are limited. Some of these work through endowed positions at universities, but we also see some who create foundations dedicated to funding directed at research.

In the past few months I came face-to-face, or at least in the same room, as two of them: Landon Clay in Oxford for the opening of the new Maths Institute partially funded by his foundation and Jim Simons, when I visited Stony Brook and had lunch in the Simons Center for Geometry and Physics. The Clay Mathematics Institute funds several mathematicians and offers the million dollar bounty on P v NP and other open questions. The Simons Foundation supports a few theoretical computer scientists, not to mention the Simons Institute in Berkeley.

Of course the more money coming into our field, the more research we can do. But patronage does have its other side.
Patronage, and the desire for more, also shaped the work and publications of scientists. Effusive dedications to current or potential patrons can be found in almost every scholarly publication, while the interests of a patron in a specific topic was a strong incentive to pursue said topic—or reframe one's work in terms of it. Galileo, for example, first presented the telescope as a naval instrument to military- and commerce-focused Republic of Venice; when he sought the more prestigious patronage of the Medici court in Florence, he instead promoted the astronomical potential of the device (by naming the moons of Jupiter after the Medicis).
 How much do the lessons of the 16-17th centuries still apply today?

Thursday, November 14, 2013

Local Reductions

With the STOC deadline passing on Monday, now is a good time to look at the arXiv to see what has been posted since then. Hamid Jahanjou, Eric Miles and Emanuele Viola have a new paper, Local Reductions, that gives a new reduction from NTIME(t) to 3-SAT formulas of size t polylog(t). The twist to their new reduction: there is an NC0 circuit C that maps the number i to the ith clause. NC0 means every output bit depends on only a constant number of input bits. The proof uses old-fashioned parallel routing.

Should have some interesting applications. It does save a step in Williams' proof that ACC0 ≠ NEXP but the combined proofs are longer.

In other news, I've been getting several email from other CS chairs looking for students to hire as faculty in their departments. The latest CRA News is 59 pages, 50 of them are faculty job ads. It's a good year to be on the job market.

Tuesday, November 12, 2013

Four answers to the Recip problem


In my last post I asked you to solve the following question which
was from the Maryland Math Competition:

The inequalities 1/2 + 1/3 + 1/6 = 1 and 1/2 + 1/3 + 1/7 + 1/42 = 1
express 1 as a sum of three (resp. four) reciprocals.

Find five positive integers a,b,c,d,e such that
1/a + 1/b + 1/c + 1/d + 1/e = 1.

Prove that for any positive integer k GE 3 there exists positive intgers numbers d1,d2,...,dk
such that 1/d1 + ... + 1/dk.

The HS students had the following solutions.
I list the answers to part b first.  I sketch the proofs. They are all by induction.

1) Use 1/n = 1/(n+1) + 1/n(n+1).  This was the most common solution.  This leads to (2,3,7,43,1806) for part a.

2) Since the question itself gives the solution for m=2 and 3 we only need P(k) --> P(k+2)
Use 1/n =  1/2n + 1/3n + 1/6n.  This leads to (2,3,12,18,36).
One of the students later told me that knew the solution (i) but did it this way to
avoid having to multiply 42 by 43 which is needed to get part a using that solution.

3) Inductively that the largest denom n is even Use 1/n = 3/3n = 1/3n + 2/3n = 1/3n + 1/(3n/2)
Less than five students did 2b this way.  This leads to (2,3,7,63,126) for 2a.

4) If (d1,...,dn) is a solution then so is (2,2xd1,...,2xdn).
Only two student did it this way.  It leads to (2,4,6,14,84), which they both used.

NOBODY did in the non-inductive way mentioned in the last post.

There were THIRTY TWO solutions to 2b.  Several people had their part 2a and 2b not
related to each other at all.  This was far more solutions than I anticipated.
While grading I got good at adding reciprocals.
I list them in lex order along with how many people did that answer.
(This is likely approx- I may have miscounted a bit, but its basically right)

(2,3,7,43,1806) - 91 (linked to solution 1 above)

(2,3,7,48,336)  - 3

(2,3,7,56,168)  - 1

(2,3,7,63,126)  - 6 (linked to solution 3 above)

(2,3,7,70,105)  - 1

(2,3,8,25,600)  - 1

(2,3,8,30,120)  - 1

(2,3,8,32,96)   - 6

(2,3,8,36,72)   - 5

(2,3,8,42,56)   - 11

(2,3,9,21,126)  - 2

(2,3,9,24,72)   - 4

(2,3,9,27,54)   - 3

(2,3,10,20,60)  - 5

(2,3,11,22,33)  - 1

(2,3,12,15,60)  - 1

(2,3,12,16,48)  - 1

(2,3,12,14,84)  - 2 (linked to solution 4 above)

(2,3,12,18,36)  - 12 (linked to solution 2 above)

(2,4,5,25,100)  - 3

(2,4,5,30,60)   - 1

(2,4,6,14,84)   - 3

(2,4,6,16,48)   - 1

(2,4,6,18,36)   - 2

(2,4,6,20,30)   - 1

(2,4,7,12,42)   - 4

(2,4,7,14,28)   - 2

(2,4,8,12,24)   - 6

(2,4,8,10,40)   - 2

(2,5,6,10,30)   - 1

(2,5,6,12,20)   - 2

(3,4,5,6,20)    - 3

Monday, November 11, 2013

A problem on Reciprocals

(I thought I had posted this a while back but I can't find it in past blogs
so I think I did not. I DID post a diff problem on reciprocals.)

Here is the question I graded a while back on a  Maryland Math Olympiad.
I request that you do it and post your answer as a comment- I'll be curious
how your answers compare to the students who took it.
I will post the solutions the students used in my next post and comments
on how they were similar or different than yours.
The students had two hours to do five problems.
This was problem 2.

The equalities 1/2 + 1/3 + 1/6 = 1 and 1/2 + 1/3 + 1/7 + 1/42 = 1
express 1 as a sum of three (resp. four) reciprocals.

PART A: Find five distinct positive integers a,b,c,d,e  such that

       1/a + 1/b + 1/c + 1/d + 1/e = 1.


PART B: Prove that for any positive integer k  GE 3 there exists k distinct positive intgers numbers d1,...,dk such that

1/d1 + 1/d2 + ... + 1/dk = 1.

Thursday, November 07, 2013

A Theorist Goes to SOSP

Monday I attended the 24th Symposium on Operating Systems Principles, the lead conference for computer systems research. Why would a nice theorist go to SOSP? Trying to recruit a few good systems faculty for Georgia Tech.

I really enjoyed the day in ways I didn't expect. I found several of the talks interesting, even from a theory perspective. Austin Clements, in the first and one of the best paper talks, said he had a theorem and proof (roughly if operations scale there is an implementation that scales well on multicores), though purposely left the formalization and proof out of the talk and focused on implementations. Kay Ousterhout built on some theoretical tools for job scheduling. In a talk after I left, a group from Texas takes a step towards practical proof-based verifiable computing. I never expected to be cited in a SOSP paper.

When I go to a theory conference I see so many people I know that I don't spend enough time meeting new people. At SOSP, I knew a handful of people and just had a great time talking to people I haven't met before, particularly students.

Only thirty papers get presented in single track in this conference held every two years. STOC/FOCS accepts over 300 papers in the same time period. Having an SOSP paper is a really big deal. Despite having only thirty talks and traditionally held in hard-to-reach places (this year an hour and a half drive from Pittsburgh), there were 628 attendees split 42% students, 42% non-student academics, 15% industry and one member of the press.

The 2013 SOSP is the first ACM conference will fully open proceedings and the authors retained full rights to their paper, the gold standard espoused by many in our community. It didn't come cheap, the conference put up $1100/paper to the ACM to pay for the privilege.

Tuesday, November 05, 2013

My Pope Number is 2: The Smaller World Hypothesis

I proofread Piergiogrio Odilfreddi's book (which is on Lance's List of Favorite Complexity Books) for which I got a generous acknowledgment. I have also
visited him in Italy, though not for a while. 

Benedict.Pope Emeritus (I think that's what he is still called) broke his silence with a letter to Odilfreddi, see here.

Hence I am two handshakes away from Pope Benedict.  It used to be said that there were Six degrees of separation-- for all people a,b there is a path of length at most 6 that links them. The graph varies with you you ask, but it tries to pin down that a and b know each other.

Is six now too big? One measure is how many Google hits
`X degrees of separation' gets
  • Six degrees gets 1,760,000 hits
  • Five degrees gets 97,300 hits
  • Four degrees gets 159,000 hits
  • Three degrees gets 605,000 hits
  • Two degrees gets 843,000 hits
The last one may not be quite fair- there was an episode of Pokemon
with the title `Two degrees of Separation' and also a company with that name.


How well two people know each other has to be defined carefully.

  1. Erdos Numbers- Put an edge between a and b if they have a paper together.
  2. Bacon Numbers- Put an edge between a and b if they appear in the same movie.
  3. Handshake Numbers (I am not sure its every been called that)- Put an edge between a and b if they have shaken hands.
  4. knows-number (likely not defined). Put a DIRECTED edge from a to b if a will return b's phone calls and/or email.
  5. Twitter Numbers (Not sure if its ever been defined). But a directed edge between a and b if a follows b on twitter.
Odilfreddi may be an articulation point in the handshake graph or the knows-graph since he is in math AND known to the public (at least in Italy) as an outspoken atheist, so he connects two worlds. Another articulation point might be David Seetapun who has a PhD in computability theory (he worked on Recursive Ramsey Theory which is how I know of him), Finance (Goldman Sacks), Gambling in Las Vegas, and swordfish fishing (he won the Golden Fly Tarpon Tournament). He may be the key to connecting mathematicians to fisherman.

The following is probably known but I couldn't find it- what is the longest distance between two websites (number-of-links to go from one to the other)?
The average? Are these numbers getting larger or smaller?

ADDED LATER: Christian Sommer emailed me the following two
RELEVENT links:

Diameter of the web and

Tools to study the web graph

The first link claims the avg diameter of the web is 19.


Friday, November 01, 2013

Andrzej Mostowski (1913-1975)

Andrzej Mostowski was born 100 years ago today. While Mostowski worked in many areas of logic, including early fundamental work on model theory, for our readers he's best known for co-discovering the arithmetic hierarchy, sometimes called the Kleene-Mostowski hierarchy.

The arithmetic hierarchy has a few different equivalent definitions but let's use one based on computability. We define inductively there hierarchies, Σi0, Πi0 and Δi0. Σ00=Π00=Δ00 are the computable sets and
  1. Δi+10 are the sets computable with a Σi0 oracle.
  2. Σi+10 are the sets computably enumerable with a Σi0 oracle.
  3. Πi0 = co-Σi0.
In particular, Δ10 are the computable sets and Σ10 are the computably enumerable sets. The halting problem is Σ10-complete under computable reductions, the set of Turing machines that accepting infinite sets are Π20-complete.

We completely know the structure of the arithmetic hierarchy, for i > 0, Σi0 ≠ Πi0 and for i ≥ 0, Δi0 = Σi+10 ∩ Πi+10.

The arithmetic hierarchy inspired the polynomial-time hierarchy in complexity theory. Unlike the arithmetic hierarchy, separations in the polynomial-time hierarchy remain open and any separation implies P ≠ NP. While we have relativized worlds which do quite a few different separations and collapses in the polynomial-time hierarchy the following remains open: Does there exist a relativized world where the polynomial-time hierarchy looks like the arithmetic hierarchy, i.e., for i > 0, Σip ≠ Πip and for i ≥ 0, Δip = Σi+1p ∩ Πi+1p?

Monday, October 28, 2013

University of Maryland Job Posting Mentions Quantum Computing explicitly!

The University of Maryland at College Park has its job posting up (its been up for a while). You can look at it here. I It lists THREE areas but says that they will take applicants from any area. This is believable since they only listed three. Had they listed (say) seven then I would not believe they are looking at other areas. What is the X such that if they list X then you believe they will take from other areas but if you list X+1 then you don't?

The three areas listed are:

  1. Cybersecurity
  2. Quantum Computing
  3. Natural Lang. Proc.
All three of these seem more particular than I usually see in job postings. That is, I've seen things like  Systems, Theory, AI. SO- is this unusual? I don't quite know--- I haven't been on the market for a long time.

Thursday, October 24, 2013

Science and Humanities

David Hollinger, a historian, wrote a recent Chronicle Review article The Wedge Driving Academe's Two Families Apart: Can STEM and the human sciences get along?, one of a number of articles I see talking about the connections between science and humanities and the future of humanities at universities.

Most scientists do find great value in the humanities and I would hope vice-versa. But when funds get tight, different fields talk about their relative importance--it happens between science and humanities broadly, it happens between theory and systems in CS departments with limited slots to hire.

I feel badly for humanities these days. In a tight job market, students and parents think hard about doing a humanities major while universities are trying to find ways to cut costs. I don't have a solution--right now the job market calls for more computer scientists than English majors, but I would hate to see an intellectual core of our academic world shrink away.

Humanities are cheap. A provost once said to me it costs the same to hire five philosophers as one physicist once start-up costs and salary are considered. We should find a way to keep funding the humanities while maintaining the strengths across all fields.

Pushing the bounds of human wisdom is important, whether it be in chemistry or classics. Only when we push in all directions does the ball of knowledge truly expand.

Monday, October 21, 2013

Teaching without a net

As a grad student I was teaching the linear-time Median finding algorithm and I FORGOT
that I needed to solve the more general problem of selection. After less than a minute
of trying to see what was wrong I told them
I am sure that Median IS in linear time. I will consult sources  and redo this tomorrow.
I then did the rest of the lecture (which didn't require knowing the Algorithm for Median) and the next day I did the linear Median Finding Algorithm correctly.

Note that I was teaching well known material. So I KNEW that what I was saying was true even if I couldn't  prove it. I also KNOW that I could look it up. I was TEACHING WITH A NET.

When I taught Grad Algs a few years ago I sometimes didn't quite know how the PROOF went  BUT I knew that the STATEMENTS I made were correct, and the algorithms and proofs were out there. In one case I emailed the original author with a subtle point I was stuck on. (It really was subtle- the author himself had to think about it). TEACHING WITH A NET

Last semester some of my Ramsey Theory course was taught WITHOUT A NET. Not in termsof the statements of theorems, but in my attempt to find easier proofs of theorems--- sometimes my alleged proof DID NOT WORK. And there was no book I could consult, nor person I could ask, to help me out on these new ``proofs''. One of my attempted simplifications (of the Canonical Ramsey Theory) DID NOT pan out in the end.

This semester  I am teaching an honors interdisplinary course on Fair Division (nicknamed 'Cake cutting'). I've pulled material from a  variety of different subfields (math, CS, AI. Yes AI!). So I have put some things together that are ``new''(not worth-publishing-new but new in some sense). Some of them have been wrong, or to be more fair, not quite right. But WHO CAN I ASK? Nobody! This is truely teaching WITHOUT A NET. I have made about 2 incorrect statements (both of which were prefaced with `this might not be quite right') but the bigger effect is that every day I wonder if what I am saying is correct.
The effect on the actual course is mininal-- but my mentality going in ``will I make a mistake today that I cannot recover from'' is... interesting.

What to do if you are wrong? Own up to it ASAP. Every minute you fumble around you lose the classes interest.

Is the course working? I think so-- they are learning and having fun. It helps that they are honors students who chose to take this course.

Wednesday, October 16, 2013

2013 Fall Jobs Post

Time again for the annual fall jobs post. As always the best places to look for academic CS positions are the job sites at the CRA and the ACM. Also check out the postdoc and other opportunities on the Theory Announcements site and the Intractability Center. It never hurts to check out the webpages of departments or to contact people to see if positions are available.

I encourage everyone who has a job to offer in theoretical computer science at any level to post links in the comments.

Faculty hiring has rebounded nicely and with computer science enrollments expanding, it should continue to be quite robust. Postdocs will still be down from a few years ago.

Good luck to everyone in the market. I look forward to seeing your names in the 2014 spring jobs post.