Wednesday, April 17, 2013

The Golden Ticket

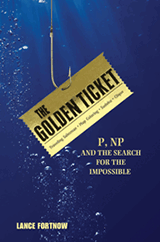
Today is the official publication date of my first book The Golden Ticket: P, NP and the Search for the Impossible by Princeton University Press, though the book has been available on Amazon and in some bookstores for a couple of weeks now. This book takes a non-technical tour of our favorite open question through a series of stories and examples, covering P, NP, NP-complete, the "beautiful world" if P = NP, and how to deal with hard problems since we surely don't live in that world and a bit of history, cryptography and quantum. How "non-technical": I never actually define P and NP and avoid formulas and terminology except as needed to describe circuits and Cook's theorem.

I spent three years on this book project, building on my CACM survey. Thanks to all of you readers for your support, your suggestions for maps (some of which I used), titles and epigraphs (none of which I used).

You can keep up with all the happenings of the book on its own twitter and website.The Golden Ticket has already received some nice reviews. You can also check out an article I wrote for the Daily Dot and podcasts interview at  Wild About Math and the New Books Network. There are Japanese and Chinese translations in the works.

Hope you enjoy the book, recommend it all all your friends and help preach the gospel of P v NP.

Monday, April 15, 2013

Post Mortem on an April Fool's day joke

Recall that on April Fools Day I had a post about R(5) being discovered via a collaboration of Math and History. Many readers emailed me asking how many people were fooled (apparently they weren't!). I can't tell if it fooled ANY of my astute readers, though I hope it amused them. I CAN tell how many of my STUDENTS if fooled. I did an experiment on my class for which I CAN report the results.

  1. All semester I gave would say things like there has been some progress on R(5), but I'll talk about that later
  2. On March 28 I gave them my paper Ramsey Theory and the History of Pre-Christian England: An Example of Interdisciplinary Research and told them that I was going to do an experiment with the flipped classroom concept (this is Real educational thing)- they would read the paper, and on Tues Apr 2 I would give them a quiz on it (to make sure they read it) and we would discuss it.
I DID give them a quiz, but I asked them to NOT sign it so it was more of a survey. Here is a summary of the questions, the stats on it, and what to make of it. 17 people took the quiz (the class has 16 and some auditors.)
  1. When did you Realize it was a hoax?
    1. When I first took this quiz: 5
    2. When I saw that Fifty shades of Grey was one of the references: 1
    3. When I went to the website that was supposed to have R(5) and it revealed the hoax: 3
    4. When I saw the name H.K. Donnut: 2
    5. When I read your April 1 blog: 1
    6. When I heard other students talk about it (though I kind of knew anyway): 4
    7. When I read the title: 1
    UPSHOT: I would count answers 1,2,3 as being fooled. So NINE were fooled. An earlier proofreader believed it because he wanted to so badly.
  2. Was it okay to have you read a hoax paper? (NOTE: My wife thought NO.)
    1. This assignment was awesome!: 9
    2. Liked learning to not always belief a prof: 1 (When I tell him the Large Ramsey Theorem can't be prove in PA will he say That's bullshit man!):
    3. Assignment was okay (I could tell these people were not amused): 7
    4. Okay as far as it goes, but 10 pages! C'mon, that's too much: 1 (This is quite fair, but it was an easy read).
    UPSHOT: I all it a success!
  3. Which of the names are Real and which did I make up?
    1. Eugene Wigner. REAL. Fake:4, Real:13. Name does sound funny.
    2. Herbert Scarf. REAL. Fake:9 Real:8. Real name that fooled the most people.
    3. Samuel Harrington. REAL. Fake:1 Real:16
    4. Dorwin Cartrwright. REAL. Fake: 6 Real: 11. I thought this would fool more people.
    5. Frank Harary. REAL. Fake: 3, Real: 14 (One thought I misspelled the real name. I didn't, but given my bad spelling, and the nature of the name, I can see why they thought so.)
    6. Charles Percy Snow. REAL. Fake: 5, Real: 12
    7. Jacob Fox. REAL. Fake:3, Real: 14. I've met him, he's real!
    8. Sandor Szalai. REAL. Fake: 4, Real: 13. Looks fake to me.
    9. Paul Erdos. REAL. Fake: 0, Real: 17. Seems like a mythical figure.
    10. Paul Turan. REAL. Fake: 3, Real: 14. One thought it was a play on Turing.
    11. Vera Sos. REAL. Fake: 3, Real: 14. I'm surprised people thought this name is real- I wouldn't have.
    12. Sir Woodson Kneading. FAKE- It's an anagram of Doris Kearns Goodwin, historian. Fake: 10, Real: 7. I'm amazed that 7 thought it was real.
    13. H.K. Donnut. FAKE- It's an anagram of Don Knuth. Fake: 13. Real: 4. Looks so fake it has to be Real? I was originally going to use Hal D.K. Donnut which is an anagram for Donald Knuth. I still don't know which looks more real.
    14. Moss Chill Beaches- FAKE- it's an anagram of Michael Beschloss, a presidential historian (He studies presidents, he is not, himself presidential). Fake: 13, Real: 4. My most fake looking name.
    15. Tim Andrer Grant- FAKE- It's an anagram of Martin Gardner. Fake: 5, Real:12. Tim is a reasonable first name, Grant is a reasonable last name, and Andrer--- well, middle names are sometimes weird.
    16. Alma Rho Grand- FAKE- It's an anagram of Ronald Graham. Fake: 14, Real: 3. My favorite fake name.
    17. D.H.J. Polymath- FAKE, but not my invention. It's used on the Polymath paper that proved the Density Hales Jewitt Theorem using elem methods (see here). Fake: 12, Real: 5. The people who thought it was real were either kidding OR read the question as a trick question Fake name that BILL MADE UP-- this is a fake name but BILL didn't make it up.
    18. Ana Writset- FAKE, It's an anagram of Ian Stewart. Fake: 4, Real: 13. Fake name that fooled the most people.
    19. Tee A. Cornet- FAKE- It's an anagram of Terence Tao. Fake: 8. Real:9. Is Tee anyone's first name?
    20. Andy Parrish- REAL. Fake: 1, Real: 16. I hope he's real, he's one of my proofreaders.
    21. Stephen Fenner- REAL. Fake: 1, Real: 16. I hope he's real- I taught him the construction of an r.e. minimal pair.
    22. Clyde Kruskal- REAL. Fake: 0, Real: 17. Real on a good day.
    One of the students who knew the Fake names were anagrams, and thought Dorwin Cartrwright was fake, spend an hour trying to find the anagram it was of. Can people spot fake names easily? I doubt it since many real names look fake, and many fake names look real. Along those lines, what do the stage names Clint Eastwood and Dolly Parton have in common? See here for the answer.
  4. Speculate on how I came up with the false names. Most left this blank. Some said Anagrams, some mentioned anagram-programs on the web (I did use one), some said random-name-generator pointing out that Vera Sos and Sandor Szalai look like they were produced by a not-very-good random name generator.
    UPSHOT: As Blanch Nail Roam said You can fool some of the people all of the time, and all of the people some of the time, but you can't fool all of the people all of the time.

Friday, April 12, 2013

You should apply for STOC and/or CCC travel money (students)


Once again there is some money from ACM and from NSF for students to goto STOC, and I am the one to send the applications to. The link for info on how to apply is on the STOC webpage, but I give it here as well. Note that the deadline is April 16.

ALSO there is travel money for CCC: see here (though I am NOT the one to send applications for that one).

If you are a grad student going to STOC and CCC then you SHOULD apply for both. If you are a grad student going to STOC but NOT CCC then you SHOULD apply for STOC. If you are a grad student going to CCC but not STOC then you SHOULD apply for CCC. If you are a grad student going to neither then... well, I have no advice for you.


  1. The application process is EASY.
  2. Not that many have applied so you have a chance. But see next note.
  3. THIS blog posting may make point 2 false.
  4. For STOC it was only one applicant per advisor; however, we have RAISED it to TWO.
  5. There is a priority for members of underrepresented groups. This DOES NOT just mean Women and minorities, it also means people from institutions that don't normally send students to STOC. However, you should APPLY even if you don't fit these descriptions.
  6. We prefer people whose advisor don't have the money to send them, or are at least short on cold hard cash.
  7. So what I really want you to is tell people who should want to go but either don't quite know what it is or don't have the money.
  8. The above are only priorities. We want to support students as much as we can, so we will be spending money, not hoarding it. Even if you thing you have low priority for one of the reasons above, you should still apply. And again- APPLYING IS EASY.
  9. The deadline is April 16, so get to it!
This also raises the question: SHOULD you goto STOC? YES
  1. Even if you are a first year theory grad students its good to see whats out there.
  2. Things you see may inspire you. My interest in Ramsey Theory came partially from seeing a STOC talk by Lipton or Chandra of Furst on bounds on Multiparty Comm Complexity that used the Gallai-Witt theorem
  3. You get to meet people. Note that many of the people who proved basic theorems are still alive.
  4. If you are work in complexity and also apply for the Student Travel Grant for CCC, and get both, you can goto BOTH!

Thursday, April 11, 2013

Technology and Jobs

Entertainment Weekly reported last month on the bankruptcy of the special effects company Rhythm and Hues and the troubled industry. I remarked five years ago that the special effects industry lost its ability to surprise us. Without the ability to innovate, and with most of the effects handled in software, the need for specialized talent and companies disappears.

We've always could take comfort that computation and its related efficiencies have led to more, often safer and higher paying jobs. But is that still true? The stock market has hit historic highs but the unemployment rate remains high. Are companies who pared down during the last recession realizing they don't need to hire as the economy comes back?

Erik Brynjolfsson and Andrew McAfee in their 2012 book Race Against the Machine: How the Digital Revolution is Accelerating Innovation, Driving Productivity, and Irreversibly Transforming Employment and the Economy, argue that computer technology has truly gotten us to the point where we need fewer people to perform the task at the middle of the economy. The world needs computer scientists and welders, but far less people doing mid-level professional work. On the other side, Henrik Christensen, a Georgia Tech roboticist, argues that technology will continue to produce far more jobs than it displaces.

My take: It's just too early to tell. The economy could completely turn around and near full employment. Or we can see a permanent loss in returning jobs. History doesn't seem like a good guide here.

There are so many issues tied to the current state of employment and this sense of technological efficiency replacing jobs: Is college really worth the cost? Should an undergraduate student major in a STEM field or follow their passion if it lies elsewhere? Do we need MOOCs to improve access to quality education and/or keep down education costs? Are academics the next group to meet the efficiency maker?

My oldest daughter starts college next year and I don't even know what advice to give her.

Monday, April 08, 2013

Is the rule of threes a meta-urban legend?

Roger Ebert died on April 4, 2013. Margaret Thatcher died on April 8, 2013. I have heard the urban legend that celebrities die in threes.

  1. Does anyone really believe this? Is it an urban legend that this is an urban legend?
  2. YES- there was an episode of 30 Rock based on this.
  3. NO- 30 Rock is FICTION.
  4. Whenever I've seen ``examples'' of this at least one of the three isn't a celebrity. Are politicians really celebrities? For that matter, are Movie Critics really celebrities (Roger Ebert may qualify but very few others would.)
  5. The notion of Celebrity is not well defined. People change it to make the rule-of-threes work. Can there be a rigorous definition of celebrity, perhaps based on the indegree of the I"VE HEARD OF THEM directed graph.
  6. I predict that somebody marginally famous will die in the next few weeks and someone will say its the rule of threes. But will the person who says it be serious? And will the person who dies really be a celebrity (whatever that means)?
  7. The paradox: there are so many famous people that I haven't heard of most of them.
I keep a list of old celebrities (defined as people that I have heard of-- websites of old celebrities have lots of people I never heard of) so that when they die I am NOT one of those saying I thought they were already dead. I noticed this when Dear Abby died: (1) young people asked Whose that? where as older people said I thought she was already dead. Margaret Thatcher and Roger Ebert people seemed to know they were alive.

Thursday, April 04, 2013

Gary Miller to Receive the Knuth Prize

The 2013 Knuth Prize will be awarded to Gary Miller at STOC (ACM Press Release). The Knuth prize is now given yearly for outstanding contributions to the foundations of computer science, jointly sponsored by ACM SIGACT and the IEEE TC on Mathematical Foundations of Computer Science.

In 1975, Gary Miller gave a polynomial-time algorithm for primality assuming that the extended Riemann Hypothesis is true. For a given n, if there is an x and j such that x2j mod n is not 1 or -1 and x2j+1 mod n ≡ 1 then n can't be prime. Gary showed that ERH implied that if n is composite there must be such an x ≤ O(log2 n). Given ERH one could just search all possible x and j in time polynomial in the number of bits to describe n.

Rabin noted that one could choose x at random to get a probabilistic algorithm that was correct with high confidence without any ERH assumption, now called the Miller-Rabin test. In 2002, Agrawal, Kayal and Saxena showed a polynomial-time algorithm for primality without assumption, but the Miller-Rabin test is still much faster in practice.

This is just part of Miller's contribution. From the press release:

Miller also made significant contributions to the theory of isomorphism testing—the problem of telling whether two structures are the same except for the labeling of their components.  He showed the equivalence of many different isomorphism problems to the still-open problem of graph isomorphism, and identified many special cases that could be solved efficiently. These included the problem of testing isomorphism for a special case known as bounded-genus graphs, a result he obtained with John Reif in 1980.  In 1985, in another collaboration with Reif, Miller invented the concept of "parallel tree contraction." This is one of the most fundamental primitives in parallel algorithm design with wide applications to graph theoretical and algebraic problems.

In 1984, Miller moved into the area of scientific computing. He set up the theoretical foundations for mesh generation, and was the first to design meshing algorithms with near-optimal runtime guarantees.  His subsequent research led to his breakthrough 2010 results with Ioannis Koutis and Richard Peng that currently provide the fastest algorithms—in theory and practice—for solving "symmetric diagonally dominant" linear systems. These systems have important applications in image processing, network algorithms, engineering, and physical simulations.  

Come to STOC and see Gary Miller's Knuth prize lecture. The program has just been posted and if you need financial help to attend, the student travel grant deadline is April 16.

Monday, April 01, 2013

A nice case of interdisciplinary research

(NOTE- this post is an April Fools Day post and is NOT TRUE. I a pointing this out since several people have read and and thought it was true and incorporated it into otherwise serious papers.)


All of the math and history in this post is elaborated on in my paper here.

Are there any interesting applications of PURE math to the Social Sciences or History? Scarf's application of the Brouwer fixed point theorem to Economics is one of many examples of applying (arguably) pure Mathematics to Economics. Cartwright, Harary, and others appear to have used graph theory to model social relationships; however, on closer inspection they just used the language of graph theory. In C.P. Snow's article, The Two Cultures, he speculates that there is a cultural divide between the sciences and the humanities, which may make such collaborations difficult. This points to the lack of interaction between the sciences and the humanities being a sociological problem in itself; however, we are not going to go there.

There was an application of Ramsey theory to sociology in the 1950's. In Jacob Fox's Lecture Notes in Combinatorics he tells the the following well known story:

In the 1950's, a Hungarian sociologist Sandor Szalai studied friendship relationships between children. He observed that in any group of around 20 children he was able to find four children who were mutual friends, or four children such that no two of them were friends. Before drawing any sociological conclusions, Szalai consulted three eminent mathematicians in Hungary at that time: Paul Erdos, Paul Turan, and Vera Sos. A brief discussion revealed that indeed this is a mathematical phenomenon rather than a sociological one. (Namely R(4)=18≤20.)

This is more of an anti-application since math was used to prove there was NO interesting sociology.


Recently there was a REAL application of Ramsey Theory to History, and later of History to Ramsey Theory. We summarize the results; however, the reader should look at the link above for more details.

  1. Sir Woodson Kneading, a scholar of pre-christian history of England noted that, from 600BC to 400BC, whenever 6 lords were in close proximity, war broke out (with one exception). Either 3,4, or 5 of them formed an alliance against the rest, or 3,4,5, or 6 hated each other and went to war. The exception: all six formed an alliance. Kneading hired a CS grad student, H.K. Donnut, to verify the data. (Note that they really used R(3)=6.)
  2. Kneading noted that, between 400BC and 200BC, whenever 18 lords were in close proximity, war broke out. Either 4,...,17 of them formed an alliance against the rest, or 4,...,18 hated each other and went to war. Again, Donnut verified the data (Note that they really used R(4)=18.)
  3. Kneading found more results of this sort. His resuls and speculations, when translated to mathematics, are Ramsey Theoretic.
  4. Kneading wrote a 300 page book on this topic using the data that he colleced and Donnut verified (Donnut declined to be a co-author since, in his view, Kneading did the intellectual heavy lifting).
  5. Alma Rho Grand, a combinatorist, saw Kneading's book and realized that Ramsey Theory would simplify the work tremendously. Grand and Kneading wrote an article of which Kneading said My paper with Alma says cleanly in 30 pages what I said clumsily in 300 pages.
  6. Grand noticed that one of Kneading's examples had 48 lords in proximity but no war broke out. This was in an era where if 5 formed an alliance or if 5 hated each other then a war should happen. She verified that this configuration showed R(5)≥49. It is already known that R(5) ≤ 49. Hence she showed R(5)=49. (Note that R(5) was unknown before this time.)

This is a case where Ramsey Theory helped History and History helped Ramsey Theory. Hopefully there will be more.
~

Thursday, March 28, 2013

Counting Descriptions- a ``new'' complexity class

Let nσ(w) is the number of σ's in w.

We often ask our students about languages like { w | na(w) = 2nb(w) } (CFL but not REG). Lets formally define languages that are like that.

A COUNTING DESCRIPTION is a boolean combination of linear equations and inequalities involving nσ(w). For example

(na(w) ≤ 2nb(w)+3) AND NOT( nc(w) = nb(w) ).

We denote a counting description by E. Let L(E) = { w : E(w) is true } A lang L is CD if there exists an E such that L=L(E). What to make of the class CD?

The following items came out of emails between myself and Eric Allender, Dave Barrington, and Neil Immerman.

  1. CD is contained in 1-way log space and in uniform TC0.
  2. CD is incomparable to REG since (1) from above we see there are langs in CD that are not REG, and (2) ba* is not in CD.
  3. CD intersect REG is in uniform AC0
  4. Parikh's Theorem yields a large class of CD's that produce context free languages.
  5. If E is a Boolean combination of threshold and mod statement, each about a single nσ(w), then L(E) is regular
  6. The following papers may help answer some of the questions one could ask: here and here.
Are the following decidable:
  1. Given a counting description E, is L(E) regular?
  2. Given a counting description E, is L(E) context free?
Richard Beigel has shown these problems, with an unbounded alphabet size, are NP-hard. see here. I am very curious about the case where the alphabet size is bounded. Are there other (NATURAL!) classes one could ask about? NOT context sensitive since CSL contain log space. NOT the class DSPACE((log n)1/2) since that's not natural. Maybe some sublinear class would be interesting. We can also ask variants of these questions involving any combinations of the following variants:
  1. Do not allow negation.
  2. Do not allow intersection.
  3. Do not allow inequalities.
  4. Do not allow additive constants.
  5. Do not allow multiplicative constants.
  6. Only allow a bounded alphabet size.
  7. Allow other types of equations, for example n_a(w) = n_b(w)2.
  8. Allow other primitives such ast n_a(w) == n_b(w) mod 9.
  9. Have a non-uniform version of Counting Descriptions and bound the size of the formula as a function of n.

In problem 7 if you allow any poly then the problem is undecidable by the solution to Hilbert's tenth problem.

Tuesday, March 26, 2013

A Century of Erdős

The great Hungarian combinatorialist Paul Erdős was born one hundred years ago today. The big celebration will happen in Budapest in July.

It's hard to say more about Erdős than I've already said in this blog so let's recap some of those highlights.

Shiva also celebrates the centenary of Erdős and I second his suggestion to check out The Man Who Loved Only Numbers, Paul Hoffman's great biography about his life. 

Thursday, March 21, 2013

The Slot Machine Theory of Paper Submissions

Why do scientists publish so much? There is the whole "publish or perish" thing but that doesn't explain the large increase in quantity of publications. With a focus on important publications and measures like H-indices, a simple publication in a conference often won't help someone's career. Yet we continue to publish as much as we can. Why?

When you play a slot machine and you win, you get lights, music, sounds of coins coming out of the machine. If you lose, nothing. Lots of positive feedback if you win with no negative feedback if you don't.

If you submit a paper and it gets accepted into a conference, you feel excited. Excited to see your name on the list of accepted papers. Excited to update your CV and to give that talk or poster that only those few who's paper was accepted get to give.

If your paper is rejected, nothing. You don't list rejected papers on your CV. Nobody will even know you submitted the paper. And you can just take that paper and submit it to another conference. Lots of positive feedback if your paper is accepted with no negative feedback if it isn't.

Some people might argue the analogy doesn't work since slot machines are arbitrary and random. Those people have never seen a program committee in action.

Tuesday, March 19, 2013

Will they use EasyPope to pick the Pope in 2050?

AP press 2050: The new pope was elected in just 2 hours using EasyPope, the software based on EasyChair, software designed to deciding which papers get into a conference. The new Pope was quoted as saying How did they manage in the old days actually Flying to Vatican to elect someone. This just seems silly.

(I do not know which is more unrealistic: That the Pope will be picked this way or that there will be an AP press in 2050.)

The recent Papal election was done the old fashioned way--- in person. Could they have done it over the web? Perhaps each Cardinal gives each cardinal (except themselves) a number between 1 and 10 for how good they would be, and a number between 1 and 3 for how confident they are in their vote.
Or a more complex system like e-harmony uses?

I doubt this will change anytime soon, and I doubt that it should. So what are the PROS of each way to meet? Some of this was covered in the Net vs Jet discussion.

PROS of meeting in person:

  1. With current technology (and this may change) its easier to have a back and fourth in person. Even now this is possible with teleconferencing, though I wonder if this would work with the 115 cardinals.
  2. You can read peoples faces and enthusiasm.
  3. There are things that can come up and be discussed that you may not have thought of if you were just alone at your computer.
  4. Technology fails sometimes.
  5. Time limited- really has to end (Papal Elections can go on for a while; however, one of the reasons for the Papal Enclave is to FORCE them to get a Pope relatively soon.)
  6. Builds connections. Recall the famous quote:
    As a society we are gaining efficiency but loosing connectivity
  7. The meeting gives you a global view of the issues.
PROS of meeting just on line.
  1. Money and Time are saved.
  2. Environmental concerns of flying
  3. Less likely to have Group Think set in.
So- which types of meetings are better for which events? And what is the criteria? Is the goal to have a better decision in the end? This is only one goal- the connections formed at the meeting are valuable also.
  1. Papal Election. There are so many candidates and so many issues that I think in person is better. I also think it won't change--- NOT because the Vatican is Tech-Shy (the last Pope had a Twitter account) but for the reasons above.
  2. The Maryland Math Competition. We used to meet four times a year, then two, and now its down to zero--- its all online now. We will go back to two meetings a year--- having someone explain a problem and its solution to you is much better than email. Note that for this a meeting is a time sink but not a money sink. A Memory--- my first year on the committee we met at the end for Pizza and Beer and they got me a non-alcoholic beer (since they knew I didn't drink). They were welcoming me into the club. By contrast I don't even know whose on the committee anymore---- just their email addresses.
  3. Program Committees- The money and time involved in getting everyone to the same place is rather a lot so I suspect these will be mostly online. I know there are some exceptions, and some meetings of subsets of the committee. At one time the COLT meeting was held AT the STOC conference where everyone would be there. Even so, it seems like the advantages of in-person are out weighted by the time and money.
  4. Conferences themselves. Could all be videotaped an available (some are) but somehow its hard for me to really GOTO an online talk.
  5. Faculty meetings. Sometimes when we try to resolve an issue online the emails just go on forever. Best to just meet and get it over with.
  6. Grad Admissions. Its now online. I miss the days when we would meet with paper folders in front of us and order a pizza.

Friday, March 15, 2013

Goodbye Old Friends

We had two terrible losses this week. Not people but websites, Intrade and Google Reader.


The corporate auditors for the real-money Irish prediction markets site Intrade found improprieties with payments to the late founder John Delaney and have effectively shut down the site, probably for good. I never bet money on Intrade but they made their bet data easily available. I used Intrade data to power my electoral markets map, possibly the most accurate predictor of elections, at least until Nate Silver came along. Even then our map updated in real time based on new information reflected in market prices, while Nate had to wait for poll data. I also used Intrade generated graphs of prediction market prices in dozens of talks I've given over the past decade. There are other sites for prediction aggregation but painful to lose the granddaddy of them all.

Google announced it is closing down Google Reader, Google's newsreader on July 1. I find Reader invaluable for keeping up with the theory blogs, especially those that don't post that often (I'm looking at you Scott and Luca) as well as a various collection of other blogs and my daily Dilbert. Not to mention the 2241 people who subscribe to this blog on Google Reader. There are alternatives (I'm trying Feedly) and I will be more vigilant on sharing posts on Twitter and Google+ but the real question is to why do fewer people use Google Reader. Is the flood of stuff on the Internet gotten so large we don't even try to keep up with it?

Wednesday, March 13, 2013

Turing Award to Shafi and Silvio

The 2012 ACM Turing Award, the highest honor in computer science, will be given to MIT cryptographers Shafi Goldwasser and Silvio Micali. From the press release:
Working together, they pioneered the field of provable security, which laid the mathematical foundations that made modern cryptography possible. By formalizing the concept that cryptographic security had to be computational rather than absolute, they created mathematical structures that turned cryptography from an art into a science. Their work addresses important practical problems such as the protection of data from being viewed or modified, providing a secure means of communications and transactions over the Internet. Their advances led to the notion of interactive and probabalistic proofs and had a profound impact on computational complexity, an area that focuses on classifying computational problems according to their inherent difficulty.
Shafi and Silvio's paper Probabilistic Encrytion really did set the stage for modern cryptography. Their paper with Charlie Rackoff, The Knowledge Complexity of Interactive Proof Systems started my own research in that area. When I did my graduate work at MIT, I had many great discussions with Shafi and Silvio about cryptography and proof systems and I owe them much for my own research career.

Congrats to Shafi and Silvio!

Tuesday, March 12, 2013

What if they gave an exam and nobody came?

A professor tells the class that he will use the highest grade to set the curve. The students all conspire to NOT take the exam, so the highest score is 0, so they should all get A's. If you were the prof what would you do?

This is NOT hypothetical. It happened- see here.

  1. The prof gave all A's and didn't even mind it since the students learned to cooperate.
  2. The prof then changed his grading scheme.
  3. The article calls it a prisoners dilemma problem. I don't think thats right; however, it is the case that someone could have `defected'
  4. Curving an exam based on the BEST student seems odd.

Friday, March 08, 2013

Opera and MOOCS

I've really learned to enjoy opera (the art form not the browser) and while I've come to really enjoy Atlanta, the city only has a regional opera company. So I tried out the Metropolitan Opera HD broadcasts in a local movie theater here. I have to say the experience was quite amazing, the picture and sound was amazing. In many ways a better experience than watching the opera live at the Met, with close-ups and back stage interviews. It doesn't replicate the atmosphere of seeing an opera live but it does give people who don't have access to the Met a great opera experience.

Watching the opera made me think of an analogy to MOOCs. There is limited scaling we can do in a classroom or an opera house, but the Opera HD and MOOCs can scale tremendously with only moderate additional cost. A MOOC doesn't replicate the classroom experience but done well it can offer some advantages to a classroom.

So this seems like a win for the opera lover. But not every opera company benefits. I went to see the Parsifal on Met HD last Saturday instead of the Altanta Opera's Traviata. Even other great US opera companies like the Chicago Lyric might not get a huge audience if they tried broadcasting their operas in movie theaters. How does the analogy play out for universities and MOOCs?

Monday, March 04, 2013

Do we ever NEED the adv pumping lemma for Reg langs?

Recall the Pumping Lemma and the Advanced Pumping Lemma for Regular languages:

Pump. Lemma: If L is regular and infinite then there exists n such that
for all w∈ L , |w|≥ n, there exists x,y,z y≠ e, w=xyz, such that
for all i≥ 0 xyiz ∈ L.

Adv. Pump. Lemma: If L is regular and infinite then there exists n such that
for all w∈ L , |w|≥ n, there exists x,y,z y≠ e, AND |xz|≤ n,
w=xyz, such that for all i≥ 0 xyiz ∈ L.

The only difference is the bound on |xz|.

The question arises: Do you ever need the advanced pumping Lemma?
I will phrase this question rigorously.

One common way to prove that a lang is not regular is to use the pumping lemma.
Another common way is to use closure properties: To show that some L is not regular
show that L ∩ R where R is a known regular language, is not regular.
The proof that L ∩ R may be by the pumping lemma or by a further reduction.
Other closure properties may be used to.

If L is regular and f is a function from Σ to &Sigma*;, extend f to be on &Sigma*;
(f(xy)=f(x)f(y), then f(L) is regular. We denote this HOM for Homomorphism.

Given a language L in alphabet Σ we define a hierarchy over L.
Each level is a set of languages.

B(0) = {L} union EVERY regular language over Σ.

If L1, L2 are in B(i) then the following are in B(i+1):

  1. L1 ∩ L2, L1 ∪ L2, COMP(L1), L1*, CONCAT(L1,L_2).

  2. L1R = { w | w ∈ L1 } where wR is w written backwards.

  3. For every f, a function from Σ to &Sigma*;, extend f to &Sigma*; via
    f(xy)=f(x)f(y). Put f(L1) into B(i+1).

Let B(ω) = B(0) ∪ B(1) ∪ ...

RIGOROUS QUESTION 1: Is there a non regular language L such that
EVERY language in B(ω) satisfies the conclusion of the Pumping Lemma.

RIGOROUS QUESTION 2: Is there a non regular language L such that
EVERY language in B(ω) satisfies the conclusion of the Adv Pumping Lemma.

RIGOROUS QUESTION 3: Are there languages L such that, for all i, B(i) is a proper subset of B(i+1)?

RIGOROUS QUESTION 4: TRUE or FALSE: For all i there exists L such that the hierarchy is proper on the first
i levels but then collapses down to the ith level.

RIGOROUS QUESTION 5: TRUE or FALSE: For all i there exists L such that the first level where
a lang appears that DOES NOT satisfy the conclusion of Pump Lemma occurs on level i.

RIGOROUS QUESTION 6: TRUE or FALSE: For all i there exists L such that the first level where
a lang appears that DOES NOT satisfy the conclusion of Adv Pump Lemma occurs on level i.

A lang satisfying Q1 that could be proven non-reg with adv pumping lemma
(possibly with closure stuff) would be interesting in that it would be a case
where you NEED Adv Pumping Lemma.

A lang satisfying Q2 that could be proven non-reg with adv pumping lemma
(possibly with closure stuff) would be interesting in that it would lead to
other techniques to show langs not regular (such techniques may already
be known- the Myhill-Nerode Theorem may be one of them).


Thursday, February 28, 2013

Our Government at Work

Barring a surprise deal, the sequester goes into effect tomorrow. NSF Director (and soon to be CMU President) Subra Suresh announced a sequestration impact statement.
At NSF, the major impact of sequestration will be seen in reductions to the number of new research grants and cooperative agreements awarded in FY 2013. We anticipate that the total number of new research grants will be reduced by approximately 1,000. All continuing grant increments in FY 2013 will be awarded, as scheduled, and there will be no impact on existing NSF standard grants. It is also important to advise you that the Foundation is currently operating under a Continuing Resolution (CR) that will expire on March 27, 2013. 
Once the CR expires the whole NSF, and many other parts of government, will shut down. While I expect the sequestration to happen, most likely the CR will get extended.

Meanwhile last week the White House Office of Science and Technology Policy issued a memo that will require most federally funded research to be publicly available after a year. The NSF and other agencies have six months to produce a plan. According to Farnam Jahanian (NSF CISE head), the NSF will work with close consultation with academics and associations in developing its plan which may not be the same for each discipline. Purely speculating, I'm guessing something akin to what the NIH does by establishing an open repository of research papers and requiring funded researchers to post copies of their papers in that repository.

Tuesday, February 26, 2013

Enos, Oona, sqrt(3), and Aaronson


My darling does crossword puzzles and sometimes asks my help:

Darling: Bill, Slaughter in Cooperstown- whats the answer?

Bill: Enos. There was a serial murderer in a town named Cooper, and he always wrote on his victims Eternity's Not On Sale. So he got the nickname ENOS. Nobody ever figured out what that meant and he was never caught.

Darling: Another clue: Chaplin's wife

Bill: Oona. That's latin for minister's spouse. And in those days ministers were always men.

Darling. Okay. Another clue: Log man. Begins with an N.

Bill: Napier, a famous lumberjack.

Many of my readers know that, while the above answers are correct,
the reasoning behind them is fictional. In fact, the entire story is fictional.
But it IS true that when Darling sees those clues in crossword puzzles
she knows what the answer is without having any idea that Enos Slaughter is in
the Baseball Hall of Fame in Cooperstown, that Oona was the name of Charlie
Chaplin'sfourth and last wife, or that John Napier is regarded as having
invented logarithms (the history of such things is always murky).
She has MEMORIZED the answers (from years of doing crossword puzzles)
without really UNDERSTANDING the answers.

When I show my students the proof that sqrt(2) is irrational and ask
them to prove sqrt(3) is irrational, I often can't tell if they truly
understand the proof or are copying a template proof of sqrt(2).

Sometimes (and usually on harder problems) some small slip will
tell me that they are just copying since they didn't quite know
what to change. Or they may miscopy.

However, there is a deeper question here. If students memorizes the
template for the proof that sqrt(n) is irrational, and uses it correctly,
then do they understand or have they just memorized? The distinction can be
hard to discern and may not even exist. One real test is if they understand
why the same template fails on sqrt(4). For harder problems there may be
other ways to tell--- having to do with when the proof fails.

Incidentally, the reason the crossword clues above come up so often is
that the answers have many vowels in them. So, one way to immortality is
to be mildly famous and have a name with a large percentage of vowels.
Let see- gAsArch: 28% vowels not so good. fOrtnOw: The same (no wonder we coblog!),
also not so good. AArOnsOn: 50% WOW!! May his name adorn crossword puzzles for
many years to come!

Thursday, February 21, 2013

Interruptions

I got a new toy this week, the Pebble watch which I got early because I pre-ordered donated to their Kickstarter campaign. It's a little buggy and the promised apps do not exist yet, but I'm already finding the watch extremely valuable because my email, texts and phone calls show up on my watch--much easier to check the watch than pull the phone from my pocket.

With Gmail smart labels and some additional filters, most of the email that reaches my inbox actually requires my attention at some point. But often I'm in a talk or a meeting. I've trained myself to ignore the buzz of my phone and now I can see I have to ignore the buzz of my watch as well--harder to do.

Our lives just get more interconnected. Some people I hear purposely disconnect themselves to get work done. I like to deal with issues as they arise and not let them pile up. But the trick is to remember that when you are in the midst of doing something best to ignore the interrupt than act upon it.

Tuesday, February 19, 2013

Are most lower bounds really upper bounds?

Recently Daniel Apon (grad student of Jon Katz at UMCP, but he also hangs out with me) proved a LOWER BOUND by proving an UPPER BOUND. His paper is here. I have heard it said (I think by Avi W and Lane H) that MOST lower bounds are really upper bounds. Below I use the term Non-Alg Lower Bound for a lower bound that is NOT an algorithm. This is not a rigorous notion and the items below are up for debate.

  1. Time Hier, Space Hier- Diagonalization. I would call that Non-Alg.
  2. Cooks Theorem: this is an ALGORITHM to transform a Non Det TM and a string x to a Boolean Formula.
  3. All reductions can be viewed as ALGORITHMS.
  4. Parity not in AC0: The Yao-Hastad proof can be viewed as a non-alg lower bound for the depth 1 or 2, and then a randomized ALGORITHM to transform depth d to depth d-1.
  5. Parity not in AC0[3]: This is a Non-Alg lower bounds--- you show that parity has some property (not being able to be approx by low degree polys) and then you show that AC0[3] cannot deal with this property.
  6. Comm Complexity: The det lower bound on EQ is a Non-Alg lower bound. I think the randomized lower bound on DISJOINT is a Non-Alg lower bounds. Many others lower bounds are reductions to these two, and hence are algorithms.
  7. Multiparty Comm Comp: I'll just mention one result: Chandra-Furst-Lipton's lower bounds on EXACT-N for k-player Number-on-Forehead. The lower bounds shows that if there is a protocol of t bits then some structure can be colored in a certain way. Then Ramsey Theory is used. Non-Alg Lower bound I think.
  8. Decision Tree Complexity (Comparisons): The lower bounds on SORTING and MAX, are non-Alg lower bounds. The following leave-counting lower bound for
    2nd largest is sort-of a reduction to MAX but I still think its non-alg: First note that the lower bound for MAX is very strong- even the best case
    requires n-1 comps. Hence any DT for MAX has roughly 2n-1 leaves.
    T is a DT for 2nd largest. For all i=1,...,n let Ti be the subtree where xi WINS. This is a MAX tree for n-1 elements so has 2n-2 leaves. All these sets of leaves are disjoint so T has n2n-2 leaves.Hence T has height n+ log n + \Omega(1).)
  9. Decision Tree Complexity (Other queries): Algebraic Queries, k-ary queries have all been studied.
    The Algebraic Queries lower bounds use number-of-component arguments and seem non-alg. Some of the k-ary query lower bounds use Ramsey Theory to reduce to the comparison case.
  10. Branching programs and other models often reduce to comm complexity. Is that an algorithm.
  11. Ryan Williams proof that NEXP is not in ACC is really, at its core, an algorithm that does slightly better than brute force.

My Final Opinion: The above is a random sample, but it seems to be that there are plenty of lower bounds that are non-alg lower bounds. However, as more and more lower bounds are known, more and more reductions will be used and hence there will be more algorithms.

Friday, February 15, 2013

Beauty and Science

Christopher Shea wrote a recent Chronicle Review article Is Scientific Truth Always Beautiful? I would argue the answer is yes, and it boils down to Occam's Razor that the simplest explanation that fits the available data is typically the best and there is a strong relationship between beauty and simplicity.

An ugly scientific theory would have a large number of parameters which will lead, in computer science terms, to overfitting the current state of the world and almost surely such a theory would be incorrect. So every scientific truth should be beautiful.

Now the converse doesn't hold. There are far more beautiful theories than correct ones. That's the beauty of the scientific method to help sort them out. As Einstein may have said, "Everything should be kept as simple as possible, but no simpler."

In mathematics, not all correct proofs are beautiful and not all beautiful proofs are correct. But if you believe Erdős, all correct theorems have beautiful proofs, all kept in The Book.

Wednesday, February 13, 2013

The Complexity-STOC Bonanza

STOC and Complexity are co-located June 1-7 in beautiful Palo Alto, California. Both conferences have just announced their accepted papers: STOC (with PDF links) and Complexity.

Both conferences will have student travel awards. Details coming soon to the respective web sites.

On a different topic, The 2014 Nevanlinna Prize committee is still accepting nomination until May 1, 2013.

Tuesday, February 12, 2013

Proving DFA-langs closed under concat and * without using equiv to NDFA's

While teaching the Equiv of DFA, NDFA, Reg exps, I wanted to impress upon my students that the best way to show DFA-langs are closed under concat and * is to first prove DFA=NDFA and then show NDFA's closed under concat and * (which is easy). The question arises: CAN one PROVE that DFA-langs are closed under concat and star without using the equivalence to NDFA's? I emailed this informal question to Richard Beigel (my go-to guy for formal lang theory--- its a good thing he's not my go-to guy for Prog Langs since then I couldn't use go-to's.)

He emailed back the following sketches of proofs of closure that only use DFA's:

Closure under concat: states will be of the form (q,S) where q is a state of M1 and S is a set of states of M2. Start in (q0, {}) where q0 is the start state of M1. Each time a character is read advance q in M1 and advance each element of S in M2. Whenever q is an accepting state, insert M2's start set into S. Accept if S contains an accepting state of M2.

Closure under star: It is easy to modify a DFA so that the start state has no incoming edges. I'll assume that M is already in that form. State of the new machine will be a set S of states of M. Start in state {q0}. Each time a character is read, advance each state in S and then if S contains an accepting state of M insert q0 into S. Accept if S contains q0.

After complementing him on his answes I asked him him about proving Reg-exp-langs closed under complementation without using equiv to DFA's. He doesn't know how to do that, so I assume it can't be done. But is there a rigorous way to even state that?
~

Thursday, February 07, 2013

Postdocs in Computer Science

Anita Jones is troubled by the growing number of postdocs in computer science, she uses "troubling" twice in the first paragraph of her CACM Viewpoint. But is it really a troubling trend or just a natural outgrowth of a maturing field?

Theoretical computer science leads computer science in having and even embracing a postdoc culture. Nearly every graduating PhD in theoretical computer science that remains in academia takes a postdoc position before taking an tenure-track job. If anything I hear theorists lamenting a drop in theory postdocs this year with the end of the Simons postdocs and CI fellows.

Postdocs give PhDs a chance to focus on research and strengthen them for the future job market. I initially started as a two-year assistant professor at Chicago, basically a teaching postdoc. If I didn't have that opportunity my research career would have died in its tracks.

What would happen if all postdoc funding was stopped. That would lead to more funding for graduate students most of whom would have to take a non-research career especially with no postdoc positions available. Hard to see how anyone wins.

Anita and I both agree that a successful postdoc experience requires strong mentorship and inclusiveness or otherwise the postdoc is just working in a vacuum. The CRA has put out a best practices memo, worth reading for both postdocs and the people who hire them.

Tuesday, February 05, 2013

The (il)logic of fandom

(UMCP is having an REU (Research Experience for Undergradutes) this summer on Combinatorial Algorithms Applied Research. If you are an ugrad, go to that site and see if you want to apply. If you are a faculty see if you want to recommend it to some students. Deadline to apply is Feb 15.)

The Sunday before the Superbowl I spotted this curious passage in THE WASHINGTON POST which I paraphrase.

Washington Redskins fans should root for the Baltimore Ravens in the Superbowl because the two teams share many fine qualities. Both have gritty defense, soft-spoken by shrewd head coaches, underrated quarterbacks craving validation on the big stage. Neither team is flashy or has big starts--- rather they are both greater than the sum of their parts.

I interpret this as assuming Sports fans pick who to root for in a logical manner. Something like I like quality X, this team has quality X, so I will root for them. Is that how sports fans act. If it was then sports fans would change who they root for often. They do not.

So what is the logic behind fandom? Why do people root for certain teams, likely for a lifetime. Is it rational?

  1. Root root root for the home team, for it they don't win its a shame. Root for the team in the place you live NOW.
  2. Root for your childhood team. I wonder if the Chicago Cubs has more fans across the country since one of the early cable channels WGN, is from Chicago and (I think) carries Cubs games--- so you can be a transplanted Chicagoan and still watch your team. As people move around alot loyalty to your home team may fade.
  3. For College teams its common to root for the team that comes from the college you went to. This is less true for graduate school.
  4. Fair weather fans root for the team that's winning. But it is more common to have a team (perhaps your home team) that you ignore unless they are winning. So you don't choose your team based on this, but you choose weather to care based on this.
  5. The early NY Mets (early 1960's) were a terrible team but they had lots of fans. There was a loser-chic factor. The Chicago Cubs have also had that. This is rare or even nonexistent now. Everyone loves a winner.
  6. Individual players may appeal to you. Tim Teabow got some attention because of his devout Christianity. But this is rare. Its more common to get attention for negative behavior. This is more a matter of rooting for a person rather than the team.
  7. A while back some teams delayed getting any black players on them so they would still appeal to racist fans. This stopped once such teams just lost too much since they were not using that talent pool. Might someone root for or against a team because of the attitude or politics of the management? If some team took the profits and funded alternative energy for real would you root for them? What if they funded Ramsey Theory? What if they supported Same Sex marriage? I doubt a team would have a public opinion on an issue which may cause them to lose fans, though a player might.
  8. A friend of yours is ON the team so you root for the team and your friend. This is rare. But if someone on the team is from your SCHOOL- you may have a certain affinity for that person and team even if you don't know them. Whenever I hear that some pro football player is from Harvard (where I went to graduate school) I at least notice this. Its rare.
  9. In the Olympics one usually roots for their own country. What if (say) American offered the top Tennis player in the world (who was not an American) to become a citizen of the USA (and pay him for it) then he won the Gold Medal for American. (I think this is legal.) Would Americans be proud of that or feel that's not quite right? I suspect that this kind of thing will happen more often over time. While this may seem strange it already happens within a country. The NY Mets do not have more players from NY. Nor do the Baltimore Ravens have more players from Baltimore.
  10. Jerry Seinfeld once commented that we LOVE this player if he's on OUR team but HATE him if he is on another team. What has changed? His uniform. So we are rooting for clothing.

Is there a logic to who a fan roots for or not? Is there a logic to being a sports fan?

Thursday, January 31, 2013

Who do you write papers for?

Mitch Daniels, the former governor of Indiana and new president of Purdue, wrote an inaugural letter where he discusses many of the challenges of higher education. His lists several common attacks on universities and one caught my eye.
Too many professors are spending too much time "writing papers for each other," researching abstruse topics of no real utility and no real incremental contribution to human knowledge or understanding.
I write papers mainly for myself. I have my own opinions on what problems are important and where my interests and research strengths lie. One of the main draws of being a professor is having the freedom to choose our own research.

But we have to write for our peers as well. It's our peers that review and cite our papers and make decisions about grants and jobs. For the most part our peers are the only ones who read our papers.

In the end we write papers for society. Most of our papers taken individually add a small amount to human knowledge and are only of interest to fellow specialists. But taken together our research drives a field of inquiry allowing us to understand and take on new challenges. Even if we have trouble selling a specific theoretical computer science papers to a broader audience, taken as a whole theory helps us model and understand the power of computation and leads to smarter and faster algorithms on real world machines.

Tuesday, January 29, 2013

TCS online series- could this work?

Oded Regev, Anindya De and Thomas Vidick we are about to start an online TCS seminar series. See here for details, though I have the first few paragraphs below.

Its an interesting idea- we can't all get to conferences so this is a good way to get information out there. Wave of the future? We'll see how it goes.

Here is the first few paragraphs:

Ever wished you could attend that talk if only you didn't have to hike the Rockies, or swim across the Atlantic, to get there; if only it could have been scheduled the following week, because this week is finals; if only you could watch it from your desk, or for that matter directly from your bed?

Starting this semester TCS+ will solve all your worries. We are delighted to announce the initiation of a new series of *online* seminars in theoretical computer science. The seminars will be run using the hangout feature of Google+. The speaker and slides will be broadcast live as well as recorded and made available online. Anyone with a computer (and a decent browser) can watch; anyone with a webcam can join the live audience and participate.

Our goal is to make engaging talks accessible to the widest possible audience, ensuring a carbon-free dissemination of ideas across the globe.

We're still in beta, and we welcome any feedback from the community. There will undoubtedly be glitches at first, but we hope you'll bear with us and be as excited as we are at trying out the possibilities of this new medium.

Now for some more practical information:

Inauguration talk:
  1. Speaker: Ronald de Wolf, CWI, Amsterdam.
  2. Title: Exponential Lower Bounds for Polytopes in Combinatorial Optimization.
  3. Source: Paper of the same name from STOC12 with Samuel Fiorini, Serge Massar,
    Sebastian Pokutta and Hans Raj Tiwary that won the best paper award.)

Thursday, January 24, 2013

The End of a Useless Test

First a word from our sponsor: Mihalis Yannakakis is celebrating his 60th birthday this year and you are invited to the party.

From the Educational Testing Service:
The last administration of the GRE Computer Science Test will be in April 2013. The test will be discontinued after the April 2013 administration. Scores will continue to be reportable for five years.
Why is the Computer Science Test being discontinued?
Over the last several years, the number of individuals taking the Computer Science Test has declined significantly. Test volume will soon reach a point where ETS can no longer support the test psychometrically. As a result, the GRE Program has decided to discontinue the Computer Science Test. The test will be offered for the last time in April 2013
"Pyschometrically" just refers to the ability to measure abilities, mental traits and processes. Seems redundant in this context.

Bill tells me Maryland CS used to require a subject GRE but no longer does. Georgia Tech CS does not require a GRE. We have a separate PhD program in Algorithms, Combinatorics and Optimization that recommends the math subject test.

Computer Science is a broad field and can't be easily tested, psychometrically or otherwise, and the score of the subject test does not help us determine who will be a good grad student.

The regular GRE exam is not that much better. The quantitative can only help weed the weak students. The analytic score should be a good predictor but isn't. The verbal score, at least among Americans, oddly enough may have the best correlation to success in grad school, but not reliable enough to put much weight on it.

So how do I judge PhD candidates? Grades in CS and math courses taking into account the quality of the university, any undergraduate research, and the recommendation letters.

Tuesday, January 22, 2013

A New application of Ramsey Theory to a Geometry problem

All of the material summazized here is in a new paper by Gasarch and Zbarsky. You can find that paper here)

Consider the following problem:

  1. Let {p1,...,pn} be a subset of distinct points in Rd. We think of d ≤ n. How big is the largest subset X of points such that all of the distances determined by pairs of elements of X are different? Let h(d,n) be the min size of X. That is, we always have a set X of size h(d,n) with all distances between points different.
  2. Assume that no three of the original points are collinear. How big is the largest subset X of points such that all of the areas determined by triples of points in X are different? Let g(d,n) be the min size of X. That is, we always have a set X of size g(d,n) with all triangle-areas of different sizes.
(This is NOT the Erdos Distance problem where you are given n points and want to know the min number of diff distances you have.) What is know about the problem posed?
  1. The case of d=1 is known h(1,n)=Θ(sqrt(n)).
  2. Erdos said somewhat mysterioulsy (I paraphrase)
    It is easy to see that there are constants ep(d) such that h(d) ≥ nep(d). (BILL: Frankly- I do not find it easy to see.)
    Aside from that, not much was known.
Until now. Gasarch and Zbarsky have shown the following (roughly)
  1. h(d,n) ≥ Ω(n1/(6d)).
  2. g(2,n) ≥ Ω((log log n)1/2901).
  3. g(3,n) ≥ Ω((log log n)1/27804).

We believe these results are new. They were obtained using variants of the Canonical Ramsey Theorem, originally due to Erdos and Rado, and some geometric lemmas.

Thursday, January 17, 2013

Rise of the Engineer

I rarely watch TV commercials anymore but its NFL playoff time and during a game last weekend, the Ford commercial showing how a liftgate can be opened by waving a foot caught my eye.

When not showing pictures of feet, this commercial focuses on an engineer by face and name, Vince Mahe, one of four engineers featured in Ford Escape commercials.
Vince Mahe, the engineer behind the hands-free liftgate, was born in France and moved to the United States when he was 10. All around the world, Mahe noticed people often have their hands full. So Mahe and team engineered a way for people to open the liftgate of the all-new Escape with a simple kicking motion under the rear bumper.
There is also a series of new IBM commercials (can't find the videos online) where an IBM researcher walks into the frame of a commercial and says something like "I'm so-and-so and I'm an IBMer helping you analyze data to target your customers".

Wasn't long ago that companies hid their scientists and engineers, only selling the product. We're seeing a new time where engineers and scientists tackling societal problems, big and small, are more forefront and center. Not since the 60's has it been this cool to be a geek.

Monday, January 14, 2013

paperfree?- we are not there yet

Last time I taught I had to decide if I would HAND OUT the HW or just say its posted (NOTE- I post it in any case.) This may seem old fashion but I think there is some psychological value to actually giving someone a piece of paper with HW 8 on the top of it. I also thought that perhaps my students would think this a strange notion and certainly my youngest great nephew and niece (both 6) will never see an assignment on paper. My classes were of sizes 40 and 20, so this is not a burden on copying (I do go paperless for my class of size bigger than 70).

I asked around and asked the class. Much to my surprise about 3/4 in each class wanted paper. Why? Speculation:

  1. They would rather I print it out then they print it out.
  2. Having the paper serves as a reminder to do it (my psychological point.)
  3. The want to have more trees cut down, hasten global warming, since that way the planet may die before the final.
  4. The youth of today are not quite as PAPER FREE as we think.
I also asked the students Do you think that in 10 years the students will prefer just posting the HW? Only half thought so, which surprised me. I think that the paperless society is coming at us much faster than that; however, I am also surprised its not here yet. So that semester I mostly gave out paper HW. But there was something else wrong with this scheme, and in the future I won't be doing it.
  1. I copied 40 HW's and only 30 people show up for class- so that really is a waste. I assigned 12 HWs, so that's 120 sheets of paper wasted. (CAVEAT- not totally wasted- I print out other papers on the backs when I can.)
  2. There were a few times when I gave out the HW, taught a lesson, then realized I wanted to ask something different. BETTER to make up MOST of the HW before the lesson, but then adjust it and post after the lesson.

My question for you: are your classes COMPLETELY paperless at this point? PROS and CONS? Also, when will this post seem quaint and odd? I thought it already was, but my students reaction says otherwise.

Thursday, January 10, 2013

Slow Science

You likely have not heard about the Slow Science manifesto. They don't blog. They don't tweet. They give a broken link to their Facebook Page which has no posts. But they do have a point.
Science needs time to think. Science needs time to read, and time to fail. Science does not always know what it might be at right now. Science develops unsteadily, with jerky moves and unpredictable leaps forward—at the same time, however, it creeps about on a very slow time scale, for which there must be room and to which justice must be done.
Computer Science is inherently a fast discipline. Technology changes quickly and if you don't publish quickly your research may become irrelevant. We created a culture with conferences and deadlines that push us, even those of us on more theoretical end, to finish our projects quickly and publish the best we have at the next due date.

But we need to step back and take a while to view the great challenges we have in computing. Issues like privacy, big data, the Internet of things and cloud computing need time to really think of the right approach, not just short term projects. In computational complexity we have grand challenges in understanding the power of efficient computation but too often we just tweak a model to eke out another publication.

Andrew Wiles solved Fermat's last theorem by toiling on the problem by himself for several years right before the Internet revolution. Will we see a slow science success again in this new age?

Monday, January 07, 2013

Do daughtered candidates to better- Look at the Data!

Someone in my election night party predicted Obama because:
Ever since women got the right to vote (1920) if one candidate has a daughter and one does not, then the one with the daughter won. This is because they know how to talk to women. Note that Obama has two daughters while Romney has 5 sons.

With Wikipedia and the web one can actually try to VERIFY the alleged FACT that daughtered candidates beat non-daughtered. If it was true then it would be much harder to verify the conjecture as to WHY its true. The full data is below but in a nutshell: From 1920 to 2012 there were 24 election. In EIGHT of them one candidate was daughtered and the other not. In FIVE of those the daughtered one won. Is this statistically significant? NO. It would take far more trials to determine if daughtered candidates do better. And even then one can note things like Roosevelt going for his third and fourth term was unstoppable so I don't think his having a daughter put him over the top. Also, times change. We will surely one day have a female candidate so that might change the dynamic as well. The problem with trends- once you figure them out they may no longer hold.

When doing a study like this you often find OTHER data of interest: ALL of the prez candidates since 1920 had children (Harding's child was a step-son but regarded Harding as his father, hence so do I.) I then looked up prez's without kids (I didn't look at candidates--- too much work) George Washington had step kids who regarded him as their father as well as the father of our country. James Madison, James Polk, James Buchanan (our only bachelor prez) didn't have kids. Of the SIX presidents named James (the others are James Monroe, James Garfield, and James Carter) THREE of them didn't have kids! Odd but NOT stat sig.

Lessons to draw from this--- (1) Don't believe everything you hear at election parties. (2) It's harder to make false claims at parties with Wikipedia and the Web around to verify (though political candidates seem to get away with it), (3) Daughtered is now a word. (4) Things that sound intuitively reasonable may still be false (5) If you look into claims that are false you may find other things of interest.

Here are the EIGHT:

  1. 2012: Obama vs Romney: Obama has 2 daughters, Romney has 5 sons. Winner: Obama (the one with the daughter)
  2. 1948: Dewey vs Truman: Dewey had 2 sons. Truman had 1 daughter. Winner: Truman (the one with the daughter)
  3. 1944: Dewey vs Roosevelt: Dewey had 2 sons. Roosevelt had 1 daughter and 5 sons. Winner: Roosevelt (the one with the daughter)
  4. 1940: Roosevelt vs Wilkie: Roosevelt had 1 daughter and 5 sons. Wilkie had 1 son. Winner: Roosevelt (the one with the daughter)
  5. 1932: Hoover vs Roosevelt: Hoover had 2 sons. Roosevelt had 1 daughter and 5 sons. Winner: Roosevelt (the one with the daughter)
  6. 1928: Hoover vs Smith: Hoover had 2 sons. Smith had 2 daughters and 3 sons. Winner: Hoover (the one without a daughter)
  7. 1924: Davis vs Coolidge: Coolidge had 2 sons. Davis had a daughter Winner: Coolidge (the one without a daughter)
  8. 1920: Cox vs Harding: Cox had 2 sons and 2 daughters, Harding had one step-son.
    Winner: Harding (the one without a daughter)
Here is the full data. A * means that it was daughtered vs non-daughtered and daughtered won. ** means it was daughtered vs non-daughtered and the non-daughtered won.
  1. 2012: Obama vs Romney: Obama has 2 daughters, Romney has 5 sons. Winner: Obama*
  2. 2008: Obama vs McCain: Obama has 2 daughters, McCain has 2 sons, 2 daughters. Winner: Obama.
  3. 2004: Bush vs Kerry: Bush has 2 daughters. Kerry has 2 daughters and 3 step-sons. Winner: Bush.
  4. 2000: Bush vs Gore: Bush has 2 daughters. Gore has 3 daughters and 1 son. Winner: Bush.
  5. 1996: Clinton vs Dole: Clinton has 1 daughter. Dole has 1 daughter. Winner: Clinton.
  6. 1992: Bush vs Clinton: Bush has 2 daughters and 4 sons. Clinton has 1 daughter. Winner: Clinton.
  7. 1988: Bush vs Dukakis: Bush has 2 daughters and 4 sons. Dukakis has 2 daughters and 1 son. Winner: Bush.
  8. 1984: Mondale vs Reagan: Mondale has 1 daughter and 1 son. Reagan has 2 daughters and 2 sons. Winner: Reagan.
  9. 1980: Carter vs Reagan: Carter has 1 daughter and 3 sons. Reagan has 2 daughters and 2 sons. Winner: Reagan.
  10. 1976: Carter vs Ford: Carter has 1 daughter and 3 sons. Ford has 1 daughter and 3 sons. Winner: Carter.
  11. 1972: McGovern vs Nixon: McGovern has 4 daughters and 1 son. Nixon had 2 daughters. Winner: Nixon.
  12. 1968: Humphrey vs Nixon: Humphrey had 1 daughter and 2 sons. Nixon had 2 daughters. Winner: Nixon.
  13. 1964: Goldwater vs Johnson: Goldwater had 2 daughters and 2 sons. Johnson had 2 daughters. Winner: Johnson
  14. 1960: Kennedy vs Nixon: Kennedy had 1 daughter and 2 sons. Nixon had 2 daughters Winner: Kennedy
  15. 1956: Eisenhower vs Stevenson: Eisenhower had 2 sons. Stevenson had 3 sons. Winner: Eisenhower.
  16. 1952: Eisenhower vs Stevenson: Eisenhower had 2 sons. Stevenson had 3 sons. Winner: Eisenhower.
  17. 1948: Dewey vs Truman: Dewey had 2 sons. Truman had 1 daughter. Winner: Truman*
  18. 1944: Dewey vs Roosevelt: Dewey had 2 sons. Roosevelt had 1 daughter and 5 sons. Winner: Roosevelt*
  19. 1940: Roosevelt vs Wilkie: Roosevelt had 1 daughter and 5 sons. Wilkie had 1 son. Winner: Roosevelt*
  20. 1936: Landon vs Roosevelt: Landon had 2 daughters. Roosevelt had 1 daughter and 5 sons. Winner: Roosevelt.
  21. 1932: Hoover vs Roosevelt: Hoover had 2 sons. Roosevelt had 1 daughter and 5 sons. Winner: Roosevelt*
  22. 1928: Hoover vs Smith: Hoover had 2 sons. Smith had 2 daughters and 3 sons. Winner: Hoover**
  23. 1924: Davis vs Coolidge: Davis had 1 daughter. Coolidge had 2 sons. Winner: Coolidge**
  24. 1920: Cox vs Harding: Cox had 2 sons and 2 daughters. Harding had 1 step son. Winner: Harding**

Wednesday, January 02, 2013

Erdős and Turing

Only nine months separate the births of two very influential mathematicians, Paul Erdős and Alan Turing, whose centenaries we celebrate this year and last. That's where the similarities end. Turing used philosophical ideas to create models and questions that help us shape the important problems in computer science. Erdős solved combinatorial problems and developed tools and techniques in the process that the rest of us rely on. Turing generally worked alone and Erdős famously "opened up his brain" to so many that we measure our research distance to him. Turing tragically died young nine year before I was born. Erdős lived twice as long as Turing, I've met Erdős and seen him speak. We connect Turing to World War II where he helped break German codes. We connect Erdős to the Cold War that challenged travel between his native Hungary and America.

Turing's work gets celebrated in the broad computer science and logic communities. ACM's highest honor is named after Turing and we just finished a year's worth of activities in his honor. Erdős is a deity in the combinatorics community and gets his centennial conference (in Hungary of course). The most influential Erdős prizes are the ones he gave out for solving his open questions.

You've likely heard much of Turing's life over the past year. For 2013 go read an Erdős biography like The Man Who Loved Only Numbers and learn about another life well lived.

Thursday, December 27, 2012

2012 Complexity Year in Review

As we turn our thoughts from Turing to Erdős, a look back at the complexity year that was. Written with help from co-blogger Bill Gasarch.

The complexity result of the year goes to Samuel Fiorini, Serge Massar, Sebastian Pokutta, Hans Raj Tiwary and Ronald de Wolf for their paper Linear vs Semidefinte Extended Formualtions: Exponential Separation and Strong Lower Bounds (ArXiv version). It is easy to show that TSP can be expressed as an exponentially sized Linear Program (LP). In 1987 Swart tried to show that TSP could be solved with a poly sized LP. While his attempt was not successful it did inspire Yannakakis to look at the issue of how large an LP for TSP has to be.He showed in 1988 that any symmetric LP for TSP had to be exponential size. (Swart had used symmetric LP's).

What about assymetric LP's? This has been open UNTIL NOW! The paper above proves that any LP formulation of TSP requires an exponential sized LP. They use communication complexity and techniques that were inspired by quantum computing.

Runners Up
And don't forget the solution to Bill's 17x17 problem.

News and trends: The new Simons Institute for the Theory of Computing at Berkeley, the great exodus of Yahoo! researchers mostly to Google and Microsoft, the near death of Florida computer science (anyone want to be chair?), and the rise of the MOOCs. 

We remember Dick de Bruijn, Tom Cover, Mihai Pătraşcu, Ernst Specker and David Waltz, not to mention Neil Armstrong and Ray Bradbury

Thanks to our guest posters Bernard Chazelle, Yoav Freund, Andrew Goldberg, Mohammad Taghi Hajiaghayi, William Heisel, Lane Hemaspaandra, John Purtilo, Janos Simon and Vijay Vazirani.

Enjoy 2013 and remember that when living in a complex world, best to keep it simple. And try not to fall off that fiscal cliff.

Thursday, December 20, 2012

Flash Fill

Sometimes it just takes a simple new feature in a popular piece of software to remind us how computer science just does cool stuff.

Excel 2013 has a new feature, Flash Fill, where you can reformat data by giving an example or two. If you have a column of names like

Manuel Blum
Steve Cook
Juris Hartmanis
Richard Karp
Donald Knuth


You can start a column to the right and type
Blum, M.
Cook, S.
and the rest of the table gets filled in automatically.

Flash Fill is based on a 2011 POPL paper by Sumit Gulwani (later a CACM highlight). It's been explained to me as applying machine learning to binary decision diagrams.

Flash Fill allows a user to manipulate data without having to write macros or Perl scripts. Someone with no technical background can use Flash Fill and enjoy the CS goodness inside without even knowing it is there.

Monday, December 17, 2012

Goodstein Sequences (Its his 100th birthday!)

LANCE: Bill, on Dec 15, 2012 it will be
Reuben Goodstein's
100th birthday.

BILL: Is he still alive? Will there be a conference in his honor? Free Food? Cake?

LANCE: No, no, and no. But you could blog about Goodstein sequences. (thinking: or they could just look it up here).

BILL: That is a Goodstein idea. You have a Goodstein sequence of good ideas.

I first define a sequence that is not a Goodstein sequence but will be good for education. Let n be a number. Say let n=42 Base 10. We then decrease the number by 1 but increase the base by one. We keep doing this. We get

  1. 42 base 10 = 42 base 10
  2. 41 base 11 = 45 base 10
  3. 40 base 12 = 48 base 10
  4. 3E base 13 = 50 base 10 (E stands for Eleven)
  5. 3T base 14 = 52 base 10 (T stands for Ten)
  6. 39 base 15 = 54 base 10
The sequence looks like its increasing. But note that it eventually gets to
  1. 30 base 24 = 72 base 10
  2. 2(23) base 25 = 73 base 10 (the ``units digit'' is 23)
  3. 2(22) base 26 = 74 base 10
OH MY. Its still increasing. But note that it eventually gets to
  1. 20 base 48 base 10 = 96 base 10
  2. 1(47) base 49 = 96 base 10
  3. 1(48) base 50 = 98 base 10
  4. 1(47) base 51 = 98 base 10
It seems to be at 98 for a while. Indeed we eventually get to
  1. 11 base 97 = 98 base 10
  2. 10 base 98 = 98 base 10
  3. 0(97) base 99 = 97 base 10
And from there on it it goes to 0. Given n, how many iterations do you need to get to 0? This function grows rather fast, but not THAT fast. To prove that it goes to 0 you need (I think) an induction on an omega-squared ordering. The true Goodstein sequences initially write the number in base 10 but also writes the exponents in base 10 and does that as far as it can: 4 x 102 x 104 + 8 x 10³ + 7 x 10² + 8 x 102 x 101 + 3 x 100

(This is called Hereditary 10 notation.) At each iteration we subtract 1 and then turn all of the 10's into 11's. More generally we write the number in base b and the exp in base b... etc and then subtract 1 and make all of the b's into b+1's. This sequence also goes down to 0. NOW how long does it take to goto 0. The function is not primitive recursive. Also, the theorem that states the sequence eventually goes to 0, cannot be proven in Peano Arithmetic.

I use Goodstein sequences as an example of a natural (one can debate that) function that is not primitive recursive. Ackermann's function comes up more often (lots more often) but is harder to initially motivate.

So Reuben Goodstein, wherever you are, I salute you!

Thursday, December 13, 2012

The Fiscal Cliff

Unless the republicans and democrats get a deal before year's end, the country will head over the so-called "Fiscal Cliff" including a budget sequestration that will cause automatic cuts to most federal agencies. This will be a disaster for science, grants will be delayed or not awarded, perhaps even spending freezes on current funds. University presidents have banded together in my old state and new to drive this point home.

Don't panic too much about the fiscal cliff, which will be short lived if it happens at all. But the consequence may lead to deep short or long term budget cuts in science. If charitable deductions are eliminated, that can be a large hit on university endowments. Pell grants might also be in play. 

On the other hand, science and education has its friends in Washington, starting with Barack Obama. So maybe the whole fiscal mess will work out just fine for us and we can go back to worrying whether universities will be decimated by MOOCs. 

Tuesday, December 11, 2012

Book review column

(I am a bit behind on posting links to my book review column- this blog post is about the Third (of four) for the year 2012, and the fourth of four has already appeared. I'll post that one later.)

My second-to-last book review column can be found here. The file pointed to does NOT include the BOOKS I NEED REVIEWED since that has changed. For that go here.

The column has an editorial! In a book review column for CS theory books?! It is an editorial against the high prices of books and the fact that many books are NOT online. These are well known problems, so what of it? I could say why the publishers are at fault, but frankly, I don't know the economics of the book market. So instead I recommend the community to do the following:

  1. Only buy books used or at a cheaper than list price (you probably already do this).
  2. If you write a book then insist that the contract allow for it to be online for free. This is not as outlandish as it sounds: (1) Blown to Bits by Abelson, Ledeen, Lewis (which I reviewed in this Column) is a book for a wide audience--- it is a popular book about computers and society. Even so, it is available online for free here. (2) Some book companies of Math and Science books allow the author to have the book free on line.
  3. When assigning a course textbook allow them to get earlier editions that are usually far far cheaper. There is no reason to insist they get the most recent edition.
Also of interest with regard to all of this- the Kistsaeung vs Wiley case: here

Thursday, December 06, 2012

Where is the youth of TCS/Market Eq/Guest Post by Vijay

(Guest post by Vijay Vazirani.)

On
Theory Day on Nov 30, 2012
Vijay Vazirani gave a talk:
New (Practical) Complementary Pivot Algorithms for Market Equilibrium.
He was inspired by the reaction to the talk to write a guest blog
which I present here!

Where is the Youth of TCS?

by Vijay Vazirani

I have always been impressed by the researchers of our community, especially the young researchers -- highly competent, motivated, creative, open-minded ... and yet cool! So it has been disconcerting to note that over the last couple of years, each time I have met Mihalis Yannakakis, I have lamented over the lack of progress on some fundamental problems, and each time the same thought has crossed my mind, ``Where is the youth of TCS? Will us old folks have to keep doing all the work?''

Is the problem lack of information? I decided to test this hypothesis during my talk at NYTD. To my dismay, I found out that there is a lot of confusion out there! By a show of hands, about 90% of the audience said they believed that Nash Equilibrium is PPAD-complete and 3% believed that it is FIXP-complete! I would be doing a disservice to the community by not setting things right, hence this blog post.

First a quick primer on PPAD and FIXP, and then the questions. Ever since Nimrod Megiddo, 1988, observed that proving Nash Equilibrium NP-complete is tantamount to proving NP = co-NP, we have known that the intractability of equilibrium problems will not be established via the usual complexity classes. Two brilliant pieces of work gave the complexity classes of PPAD (Papadimitriou, 1990) and FIXP (Etessami and Yannakakis, 2007), and they have sufficed so far. A problem in PPAD must have rational solutions and this class fully characterizes the complexity of 2-Nash, which has rational equilibria if both payoff matrices have rational entries. On the other hand, 3-Nash, which may have only irrational equilibria, is PPAD-hard; however, its epsilon-relaxation is PPAD-complete. That leaves the question, ``Exactly how hard is 3-Nash?''

Now it turns out that 3-Nash always has an equilibrium consisting of algebraic numbers. So one may wonder if there is an algebraic extension of PPAD that captures the complexity of 3-Nash, perhaps in the style of Adler and Beling, 1994, who considered an extension of linear programs in which parameters could be set to algebraic numbers rather than simply rationals. The class FIXP accomplishes precisely this: it captures the complexity of finding a fixed point of a function that uses the standard algebraic operations and max. Furthermore, Etessami and Yannakakis prove that 3-Nash is FIXP-complete. The classes PPAD and FIXP appear to be quite disparate: whereas the first is contained in NP INTERSECT co-NP, the second lies somewhere between P and PSPACE (and closer to the harder end of PSPACE, according to Yannakakis).

Now the questions (I am sure there are more):

  1. Computing an equilibrium for an Arrow-Debreu market under separable, piecewise-linear concave utilities is PPAD-complete (there is always a rational equilibrium). On the other hand, if the utility functions are non-separable, equilibrium consists of algebraic numbers. Is this problem FIXP-complete? What about the special case of Leontief utilities? If the answer to the latter question is ``yes,'' we will have an interesting demarcation with Fisher markets under Lenotief utilities, since they admit a convex program.
  2. An Arrow-Debreu market with CES utilities has algebraic equilibrium if the exponents in the CES utility functions are rational. Is computing its equilibrium FIXP-complete? Again, its epsilon-relaxation is PPAD-complete.
  3. A linear Fisher or Arrow-Debreu market with piecewise-linear concave production has rational equilibria if each firm uses only one raw good in its production, and computing it is PPAD-complete. If firms use two or more raw goods, equilibria are algebraic numbers. Is this problem FIXP-complete?

Monday, December 03, 2012

Too Much Competition?

On Friday the New York Times ran an article on how online retailers constantly adjust prices to match their competitors. Their ability builds on many tools from computer science, from networks to algorithms, not unlike airlines and hedge funds. But is this good for the consumer?

Suppose I work for bestbuy.com and have a television priced at $500, which matches the price on amazon.com. If I lower my price to $450, than I can expect Amazon to do the same. I've gained little from lowering the price, only $50 less dollars than I had before. Likewise Amazon has little incentive to lower their price. This hypercompetition can actually lead to collusion without colluding. Hal Varian talked a similar theme of price guarantees in a 2007 Times viewpoint.

In practice, companies still lower their prices but as networks get faster, algorithms get smarter and more people shop online, we might actually see higher prices and less competition, which I believe is already happening with the airlines.